Vannarot Roeung
Recent posts by Vannarot Roeung
How to Stop AI Scrapers From Making Up Data
AI scrapers fill missing fields with real text from the wrong line of the page. We rebuilt the "Do not guess" twin-page test on a CPU: quote checks caught 0 of 7 decoys, and a 4B checker model caught them all.
Claude Sonnet 5.5: Half Opus's Price, Not Half the Bill
Claude Sonnet 5.5 costs half of Opus 5.5 per token and beats it on Terminal-Bench 4.0. At max effort, Artificial Analysis measured $7.60 per task against Opus 5.5's $5.98. Here is how effort decides your bill, and the five breaking changes to fix first.
Manus 2.0 Video Editor and Game Dev: What the Docs Omit
Manus 2.0 adds a timeline Video Editor and a Game Dev tool with multiplayer. We checked 10 official Manus pages: none gives a credit cost for either, and the server behind a multiplayer game starts at $30 a month.
Eleven v4 Is #1 in TTS. The 72% Discount Ends Oct 12
ElevenLabs' Eleven v4 took first place on the Artificial Analysis Speech Arena at 1319 Elo on launch day. It costs $0.022 per 1,000 characters until 12 October, then $0.08: here is who should switch now and who should wait.
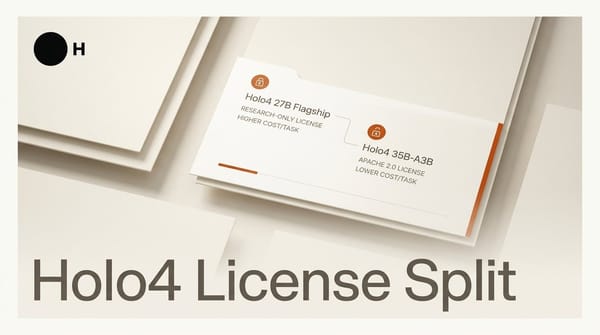
Holo4 27B vs 35B-A3B: The License Picks Your Model
H Company's Holo4 ships two open-weight computer-use models. The 27B wins on long workflows at $2.94 per completed task but is research-only; the Apache 2.0 35B-A3B is the one you can self-host commercially.
Naive-N0.5-Flash vs DeepSeek V4.1 Flash in Claude Code
NaiveAI's new MIT-licensed 309B coding model trails DeepSeek V4.1 Flash by 6.4 points on its own launch chart. Measured in the same harness, Claude Code, the gap is 2 points, and the cheaper model depends on your cache-hit rate.
Ollaya Tested: Jev-Style Decision Models on a CPU
Ollaya, the open-source runtime that serves Jev-style decision models locally, hit the Hacker News front page on 25 September. We ran three of its models on a CPU against 300 labelled examples: Laya is fastest and most overconfident, decider:0.8b the most accurate.
Do Content Credentials Survive Export? 34 Edits Tested
We ran C2PA-signed files through 34 ordinary export steps in Pillow, ImageMagick, sharp, oxipng, ExifTool and FFmpeg. Not one kept a valid Content Credential: 27 deleted it and 7 broke it.
Supabase Exposure: How to Check Your Vibe-Coded App
UpGuard found 16,326 Supabase databases with tables anyone can read, many from apps built by AI coding agents. We tested 12 common RLS setups and wrote a 15-minute audit to check your own project.
LongCat-2.5-Preview: Free in OpenCode, No Benchmarks Yet
Meituan's LongCat-2.5-Preview landed on 25 September with a 1M-token context, image and video input, and a free OpenCode tier. It costs $0.30 in and $1.20 out per million tokens direct, but Meituan has published no benchmarks yet.
How to Add Sound Effects to AI Video in 2026
Most AI video clips come out silent. Here is how to add synced footsteps, ambience and impacts in about thirty minutes, and why the licence decides the tool before quality does.
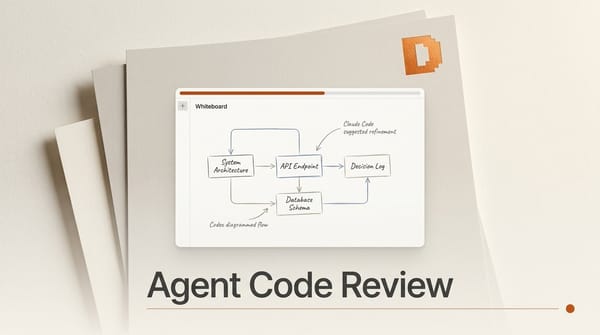
Whiteboard for Coding Agents: Setup, Limits, What It Sends
Whiteboard, an open-source app from the YC W26 startup /dev/fast, shipped on 24 September. Claude Code and Codex can draw diagrams, semantic diffs and decision logs that link back to the code. Here is how to set it up, and what leaves your machine.
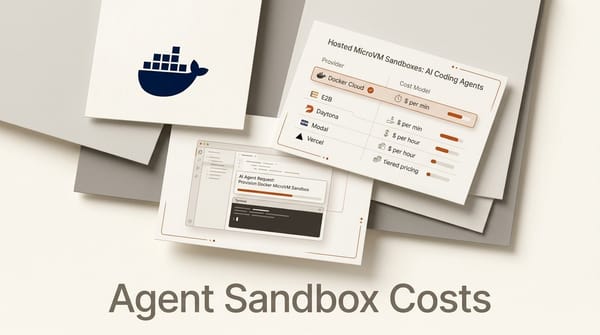
Docker Cloud Sandboxes vs E2B, Vercel, Modal: Agent Costs
Docker Cloud Sandboxes launched on 24 September at $0.14 an hour for 2 vCPUs, the lowest flat rate against E2B, Daytona and Modal. But Docker bills idle time, and coding agents spend much of theirs waiting on the model.
Real-Time AI Avatars: Gemini vs Meta vs Runway vs HeyGen
Google made Gemini 3.8 Live with Live Avatar generally available on 24 September, a day after Meta showed Muse Realtime Avatar. The pricing pages and session docs tell a different story from the launch posts.
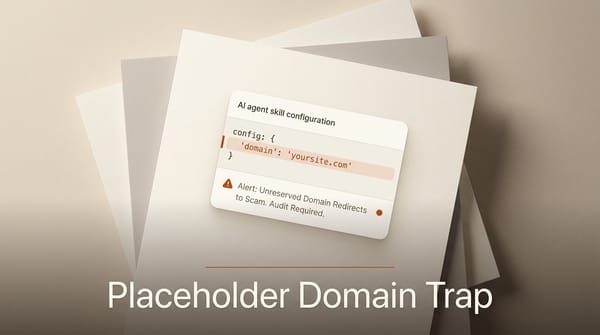
Placeholder Domains in AI Agent Skills: A 10-Minute Audit
Placeholder domains like yoursite.com appear in 349 AI agent skills and anyone can own them. We scanned 658 popular skills, found 20 hits, and wrote a 10-minute audit.
Claude Code Cloud Sessions GA: What $100 Buys
Anthropic made Claude Code cloud sessions generally available on September 23, with a one-time $100 credit on Pro and $250 on Max. The VM is free; the credit pays for model usage, and on Opus 5.5 it goes less far than it sounds.
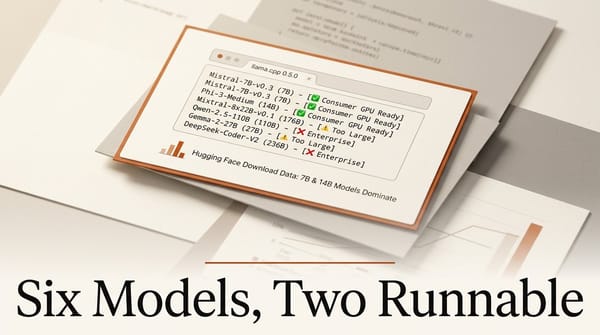
llama.cpp 0.5.0: Six New Models, Two You Can Run
llama.cpp 0.5.0 shipped on 23 September 2026 with six new model families in its release notes. The download and file-size data on Hugging Face tells a narrower story about which of them you can actually run tonight.
CLM-8B: Open Jev Rival and What Its 81.6% Counts
CLM-8B, an open decision model from Stanford and NVIDIA released on 23 September, scores candidate actions up to 9x faster than Jev. Its 81.6% DeepSWE result is 31 of 38 tasks. Here is how to run it as a verifier for your coding agent.
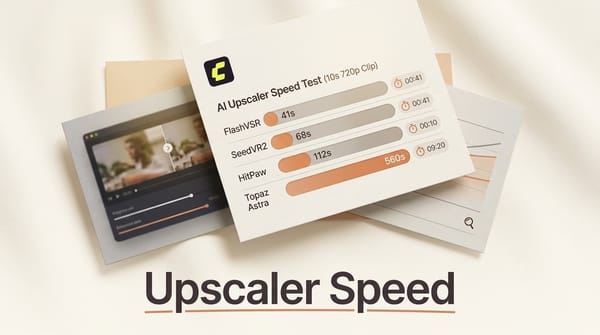
AI Video Upscalers Compared: 41s to 560s Per Clip
On the same ten-second 720p clip, the fastest AI video upscaler finishes a 1080p pass in 41 seconds and the slowest finishes 4K in 560 seconds. A 13.7x spread, read for what it means for your pipeline.
Gemini 3.8 TTS Is #1. The Price Doubles January 1
Google's new Flash TTS and Flash-Lite TTS lead Hume AI's Voice Design Benchmark. The launch price is promotional, and every tier doubles on 1 January 2027.
Comfy Router Says One API. The Matrix Says 10 Models
Comfy Router reaches frontier media models across four hosting providers by changing two strings. The coverage matrix that makes that true has ten rows, against a catalog of more than 200 models, and the default translation mode drops parameters silently.
Nemotron 3 Diarization vs pyannote: Where It Wins
NVIDIA's free Nemotron 3 Diarization averages 19% error against 20% for the paid pyannoteAI API. Dataset by dataset it wins 4 of 11, and one of those wins is on audio it trained on.
Antigravity SDK Local Models: What 97.2% Hides
Google's Antigravity SDK now runs agents on local models: Gemma 4 26B A4B through LiteRT-LM, or any OpenAI-compatible server such as Ollama, LM Studio or vLLM. We read the SDK source and the demo code behind its 97.2% local-token headline.
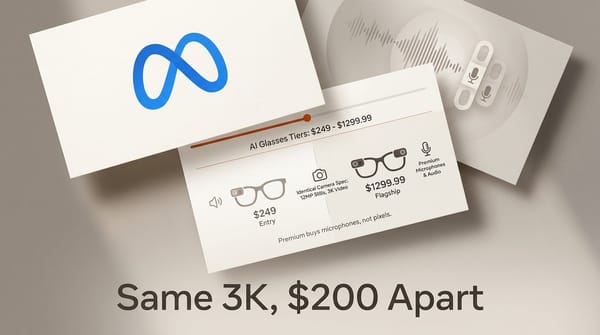
Meta's $449 Glasses Shoot the Same 3K as the $249 Pair
Meta opened Connect 2026 with six pairs of glasses spanning $249 to $1,299.99, and the pair it put on stage first cannot take a photograph. Read the spec sheets side by side and every camera-equipped pair captures the same 12 MP stills and 3K video.