Nemotron 3 Diarization vs pyannote: Where It Wins
NVIDIA's free Nemotron 3 Diarization averages 19% error against 20% for the paid pyannoteAI API. Dataset by dataset it wins 4 of 11, and one of those wins is on audio it trained on.
NVIDIA's free Nemotron 3 Diarization averages 19% error against 20% for the paid pyannoteAI API. Dataset by dataset it wins 4 of 11, and one of those wins is on audio it trained on.
ElevenLabs released Music v2.5 on 11 September 2026 and made one decision that matters more than the model: lossless downloads on every plan, including Free, which gets five a day. Two days after Suno shipped v6, the AI music fight has moved from output quality to export rights.
Ten AI tools now cover the whole podcast production line, and the cheap end got good enough that most shows should pay for exactly one seat. Every price verified against the vendor's own pricing page on September 9, 2026.
On September 8, 2026, European lab Desert Ant Labs published 18 small AI models that run entirely on a users device, with SDKs for Swift, Kotlin and JavaScript and a free tier covering the first 100,000 monthly active devices per platform.
TONE3000 launched a free, open-source plugin that streams more than 700,000 Neural Amp Modeler captures and impulse responses straight into your DAW.
Meta shipped Muse Voice Transcribe on September 1, 2026, a real-time speech-to-text model that streams transcription, diarizes 20-plus speakers, and posts a 3.1% word error rate.
Mureka released V9.5 of its AI music model, shifting focus from convincing sounds toward complete songs with stronger arrangements and more natural vocals.
Google launched Gemini 3.5 Transcribe, a speech-to-text model that detects 85+ languages, removes filler words, and reaches a 2.6% word error rate.
BreezeBlue has open-sourced Breeze TTS 2, a text-to-speech model that now ranks first among open-weights systems on the Artificial Analysis Speech Arena.
ElevenLabs archived its local MCP server repository on August 20, 2026, pointing developers to a hosted server that authenticates with OAuth rather than a copied API key.
Say It, a free and open-source macOS app, turns highlighted text into spoken audio and clones voices entirely on your own machine, with no cloud or accounts.
NVIDIA released Magpie TTS Multilingual, an open-weights text-to-speech model that speaks 12 languages and hits a 32ms time-to-first-audio, small enough to self-host inside a live voice agent.
Vocal Slice cuts audio by selecting words in a transcript, running Whisper locally so your recordings never leave your device.

Vibez is a new open-source DAW written in pure Rust, launched August 9, 2026 for Linux, macOS, and Windows, pairing clip launching with a timeline plus VST3 and CLAP plugin support.
audio.cpp 0.5 turns a pure C++ engine into a full local audio studio: expressive DramaBox TTS, Confucius4 cross-lingual voice transfer, music, and AMD ROCm support, all with no Python.
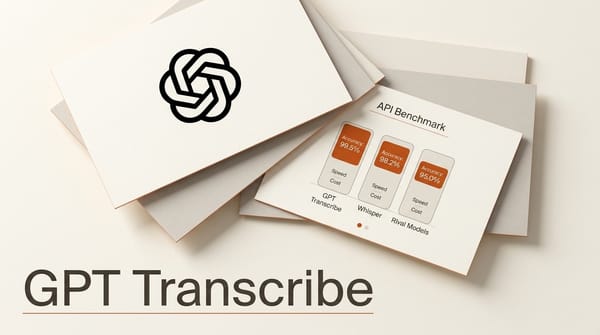
GPT Transcribe ranked against Whisper, gpt-4o-transcribe, ElevenLabs Scribe, Gemini 3 Pro, and Voxtral on accuracy, price, and the features it drops.
Audio8 TTS Preview 0.6B is an open-weights, Apache 2.0 text-to-speech model that clones a voice from a few seconds of audio and speaks 11 languages.

VoiceHop 2.0 brings sub-second, voice-preserving AI translation to any video, stream, or call as a browser extension. Here is what it does and how real-time translation compares to async dubbing tools.

Fish Audio raised $52M and made S2.1 Pro free through August 31: production-grade voice cloning across 83 languages at roughly 90ms latency, plus an open-source path via Fish Speech.
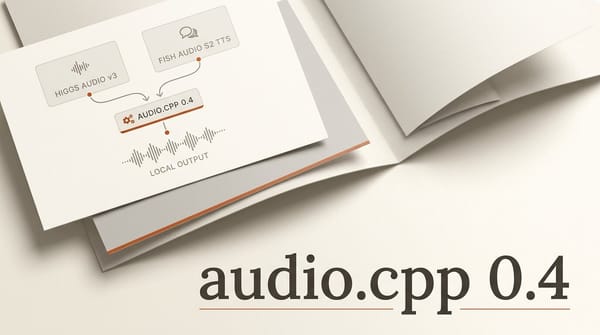
audio.cpp 0.4 adds Higgs Audio v3 4B, Fish Audio S2 Pro, and Voxtral Realtime ASR to one C++/ggml engine, running flagship text-to-speech locally on CUDA with no Python.

Alibaba's Tongyi Lab released Qwen-Audio-3.0-TTS, a hosted text-to-speech model that topped the Artificial Analysis TTS leaderboard in July 2026.

audio.cpp 0.3 adds Supertonic 3, IndexTTS2, Irodori-TTS, and MOSS-TTS to one C++/ggml engine, running local text-to-speech and voice cloning with no Python and no cloud fees.
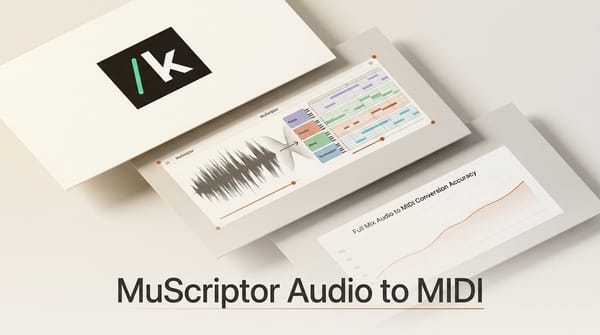
Kyutai and Mirelo released MuScriptor, an open-weight model that transcribes a full song mix into separate, editable MIDI tracks, one per instrument.

aria is a dependency-free native runtime that runs the full Stable Audio 3 text-to-music pipeline on ordinary GPUs, CPU-only laptops, and an 8GB Raspberry Pi 5, no Python required.