
Lemonade 11.0: AMD's Local AI Server Adds TTS and 3D
AMD's Lemonade 11.0 turns its local AI server into a full multimodal stack, adding text-to-speech and 3D generation alongside LLMs and image gen.
AMD's Lemonade 11.0 turns its local AI server into a full multimodal stack, adding text-to-speech and 3D generation alongside LLMs and image gen.
Branda turns any website URL into ready-to-ship, on-brand LinkedIn and X ad creatives in seconds, pulling real logos and colors via the Context.dev Brand API.
Bonsai 27B is a new open-weights multimodal model that PrismML compressed to as little as 3.9 GB, small enough to run entirely on a phone or laptop with no cloud connection.

audio.cpp 0.3 adds Supertonic 3, IndexTTS2, Irodori-TTS, and MOSS-TTS to one C++/ggml engine, running local text-to-speech and voice cloning with no Python and no cloud fees.
Mozilla released its inaugural State of Open Source AI report on July 14, 2026. Open-weight models have closed the capability gap with closed frontier systems to just 3.3 percent, while inference costs fell roughly 50 times in three years.
Vivijure is a free, open-source AI film studio you self-host, orchestrating a dozen image, video, audio, and lip-sync models behind one web interface.
Clawk gives an AI coding agent its own disposable Linux microVM, so Claude Code or Codex can run with full autonomy while your laptop stays isolated.
Generate every clip, cut them on a real timeline, add captions, and export a finished AI short without leaving ComfyUI. A full step-by-step Velorn workflow, plus how to automate it with an AI agent.
Kyutai and Mirelo released MuScriptor, an open-weight model that transcribes a full song mix into separate, editable MIDI tracks, one per instrument.
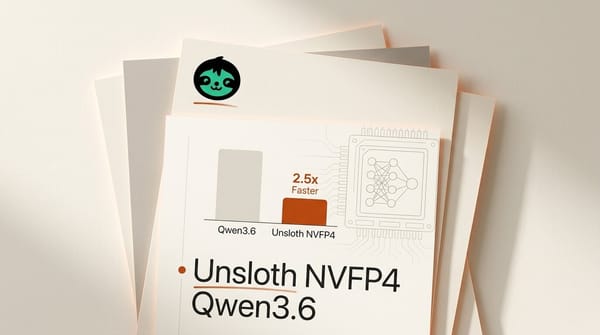
Unsloth released NVFP4 quantized versions of Qwen3.6 that run up to 2.5x faster, with the 27B model fitting on a single 24GB GPU.
ReviewFlow is a new open-source extension that moves GitLab code review inside your editor, so you can draft comments and publish merge request reviews without leaving Cursor or VS Code.
A developer released Colibri, a pure-C engine that runs GLM-5.2 (744B MoE) on a 25GB-RAM machine with no GPU by streaming experts from an NVMe SSD.

Ollama raised $88M and now serves 8.9M developers. Here is how to run open AI models locally, when to reach for Ollama Cloud, and a full getting-started workflow.

aria is a dependency-free native runtime that runs the full Stable Audio 3 text-to-music pipeline on ordinary GPUs, CPU-only laptops, and an 8GB Raspberry Pi 5, no Python required.

Hugging Face and vLLM shipped a native-speed transformers backend on July 8, 2026, serving almost any Hugging Face model at full vLLM speed with a single flag.
Mozilla AI has released Otari, an open-source, self-hosted LLM gateway that puts a single OpenAI-compatible endpoint in front of more than 40 model providers.

Rowboat is a free, open-source, local-first AI coworker built as a Claude Cowork alternative, running any model via Ollama or LM Studio.
PocketTTS-RAVEN runs text-to-speech and voice cloning entirely in a browser tab, with no server, GPU, or account, at faster-than-realtime speed.
NVIDIA has released Audex, an open-weight audio-text model that does speech recognition, translation, text-to-speech, and general audio generation in one network.
Cohere released Transcribe Arabic, an open-weight Apache 2.0 speech-to-text model built for Arabic dialects, bilingual speech, and code-switching.
Ternlight packs semantic search into a 5 to 7 MB WebAssembly bundle that runs on the CPU with no API, and it hit the Hacker News front page within a day of launch.

Tencent open-sourced Hy3, a 295B mixture-of-experts model (21B active, 256K context) under Apache 2.0. It beats GLM-5.2 at roughly half the size and is free on OpenRouter until July 21.
Meituan open-sourced LongCat-2.0, a 1.6-trillion-parameter agentic coding model trained entirely on Chinese chips. The weights just landed on Hugging Face, and it beats GPT-5.5 on SWE-bench Pro.
NVIDIA's Nemotron-Labs-TwoTower generates text 2.42x faster at 98.7% quality by adding a denoiser tower to a frozen autoregressive backbone, no retraining required.