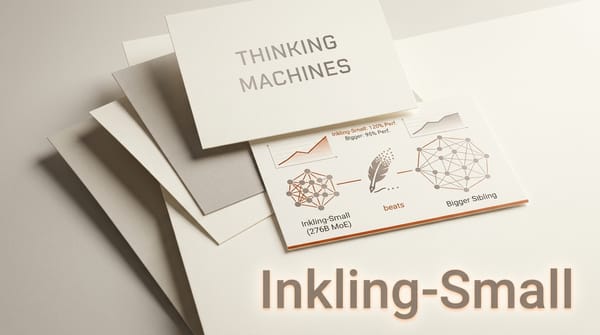
Inkling-Small: Open 276B Model Beats Its Big Sibling
Thinking Machines released Inkling-Small on July 30, a 276B open-weight MoE with 12B active params that matches or beats the full Inkling on reasoning and coding at a third the token price.
Thinking Machines released Inkling-Small on July 30, a 276B open-weight MoE with 12B active params that matches or beats the full Inkling on reasoning and coding at a third the token price.
Thinking Machines released Inkling, a 975B-parameter open-weights Mixture-of-Experts model that reads text, images, and audio. You can self-host it or fine-tune it via Tinker.

AMD's Lemonade 11.0 turns its local AI server into a full multimodal stack, adding text-to-speech and 3D generation alongside LLMs and image gen.
Bonsai 27B is a new open-weights multimodal model that PrismML compressed to as little as 3.9 GB, small enough to run entirely on a phone or laptop with no cloud connection.
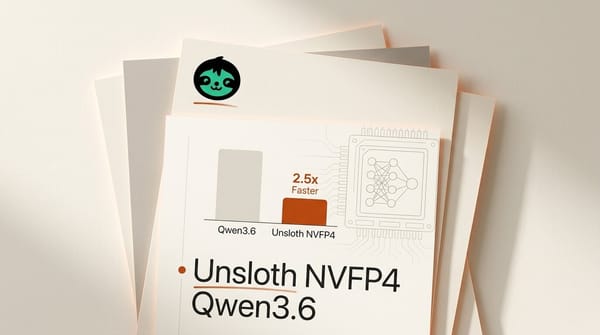
Unsloth released NVFP4 quantized versions of Qwen3.6 that run up to 2.5x faster, with the 27B model fitting on a single 24GB GPU.
A developer released Colibri, a pure-C engine that runs GLM-5.2 (744B MoE) on a 25GB-RAM machine with no GPU by streaming experts from an NVMe SSD.

aria is a dependency-free native runtime that runs the full Stable Audio 3 text-to-music pipeline on ordinary GPUs, CPU-only laptops, and an 8GB Raspberry Pi 5, no Python required.

AMD put a 128GB local AI workstation on retail shelves for $3,999. The Ryzen AI Halo runs models up to 200 billion parameters and undercuts Nvidia's DGX Spark by $700.

Run a capable AI coding agent entirely on your own machine: one open-weight model, one GPU, no per-token bill, and no code leaving your network.
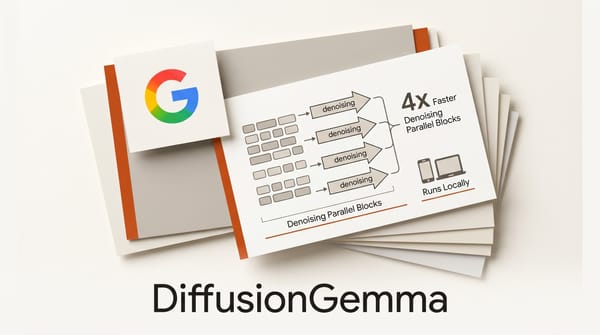
Google DeepMind released DiffusionGemma on June 10, 2026, an Apache 2.0 open model that generates text up to 4x faster by denoising blocks of tokens in parallel, and it runs on a single RTX GPU.
LM Studio released LM Link support for iPhone and iPad on June 4, 2026, through its official Locally mobile app.
NVIDIA shipped NemoClaw on June 1, 2026, a single-command installer for local AI agents on DGX Spark hardware, with multi-node clustering up to 512GB pooled memory.
WorkInProcess is a free browser-based image studio with AI upscaling and object removal. No uploads, no accounts, everything runs locally.
mistral.rs v0.8.2 delivers 3.5-5.5x faster MoE prefill on CUDA, fused decode kernels, and agentic tool-calling improvements for local LLM workflows.
NVIDIA announced DGX Station for Windows at Computex 2026, putting a GB300 Grace Blackwell Ultra chip and 748GB of memory into a desktop that runs trillion-parameter models locally.
PewDiePie open-sourced Odysseus, a self-hosted AI workspace with chat, agents, deep research, and 270+ model serving. MIT license, no telemetry.
Llama Studio v0.2.0 is a lightweight web interface for managing multiple llama-server sessions, with multi-GPU tensor splitting, shell-script configs, and auto-load snapshots.
llama.cpp release b9438 (May 30 2026) adds custom CSS injection to the built-in web UI. Operators and users can now theme the interface without recompiling.
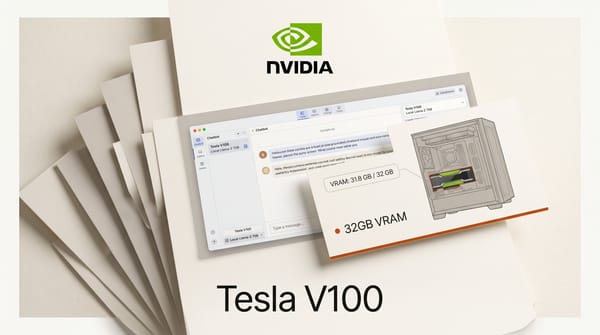
Developer Oscar Molnar installed a secondhand Tesla V100 SXM2 into his gaming PC alongside an RTX 4080, building a 32GB dual-GPU setup for under £200 total.
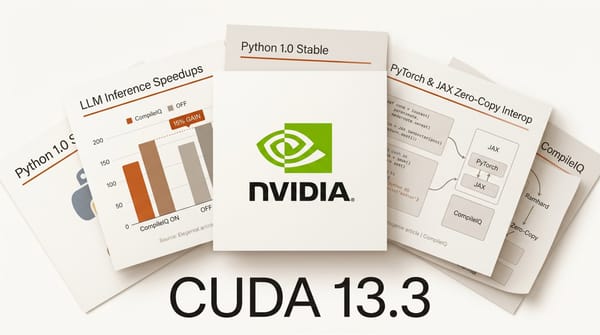
CUDA 13.3 lands Python 1.0 stable, CompileIQ for 15% LLM inference speedups, and PyTorch/JAX zero-copy. What creative AI builders gain.
OpenBMB's MiniCPM5-1B is a 1.08B Apache 2.0 LLM that ranks first on the Artificial Analysis index for small models, scoring 17.9 against Qwen3.5-2B's 16.3, runs on CPU, and supports a 131K-token context.
Google's Gemma 4 E2B proves that a 2B parameter model can handle structured JSON output, tool calling, reasoning traces, and real code review -- all running locally at zero API cost.
XDA Developers tested switching from LM Studio to llama.cpp on May 23, 2026 and found 5-20% faster inference with full model compatibility and unlocked audio features.
A solo developer just open-sourced framedex, an MIT-licensed local pipeline that indexes a year of personal video footage on a 2021 MacBook using a quantized Gemma 4 31B model running through LM Studio.