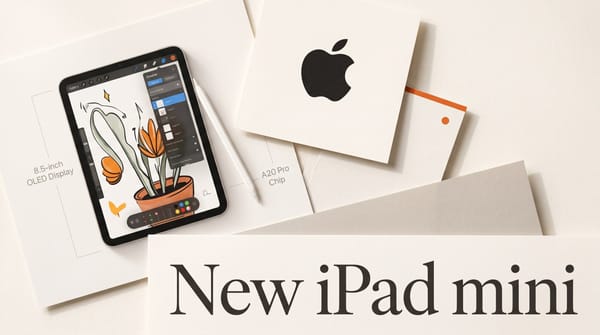
New iPad mini A20 Pro: Which Model Creators Should Buy
Apple's new iPad mini has an 8.5-inch OLED display, the A20 Pro chip and a $699 starting price. The Dual Neural Engine Apple says speeds up Draw Things is only in the $999 512GB model.
Apple's new iPad mini has an 8.5-inch OLED display, the A20 Pro chip and a $699 starting price. The Dual Neural Engine Apple says speeds up Draw Things is only in the $999 512GB model.
llama.cpp 0.6.0 ships a Hugging Face model downloader and a memory-fit estimate. We tested both: downloads work through the API today, the model browser is still a pull request, and the estimate ignores context and vision files.
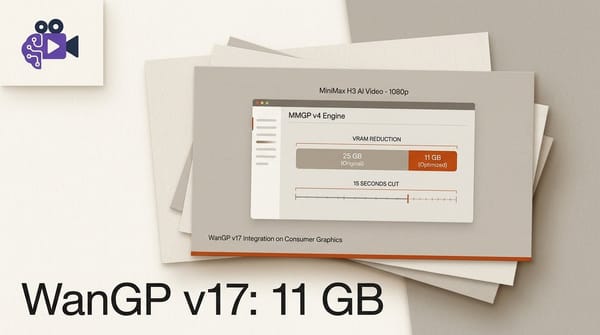
WanGP v17, released October 5, 2026, cuts 15 seconds of MiniMax H3 at 1080p from 25 GB to 11 GB of VRAM with its new MMGP v4 memory engine. Two savings are on by default; three settings you switch on yourself.
InvokeAI 7.0 alpha 1 adds video with generated sound, a rewritten canvas with PSD export, autosaving projects and semantic gallery search. What changed, which video model you can legally use, and how to install it without breaking v6.
NVIDIA's DGX Spark 64GB starts at $4,999 on October 23, while the 128GB model is now $6,950. We summed the real Hugging Face file sizes of 16 local LLM, image and video setups: 8 fit in 64GB, 8 don't, including gpt-oss-120b and NVIDIA's own Nemotron 3 Super.
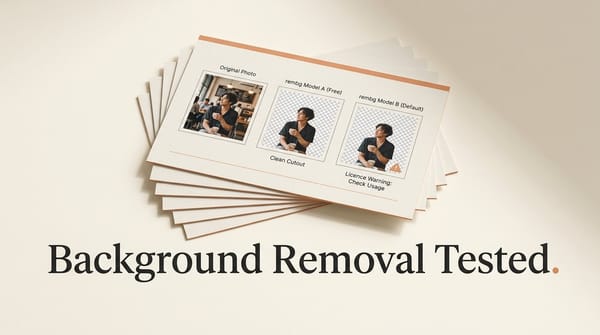
rembg's default background removal model is now BRIA's RMBG-2.0, which is non-commercial and ran out of memory on our 12 GB test machine. We scored the models that do run on 500 photos: ISNet with ViTMatte edges was the best free setup.
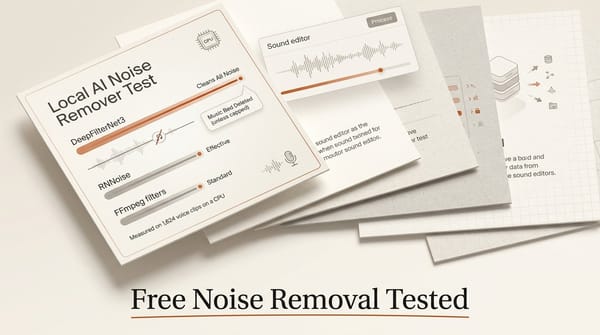
DeepFilterNet3 lifted speech quality on every noise we tested, from keyboard clatter to mains hum, on one CPU core. At its default setting it also removes a music bed almost completely, and the RNNoise inside OBS is the pre-2024 model.
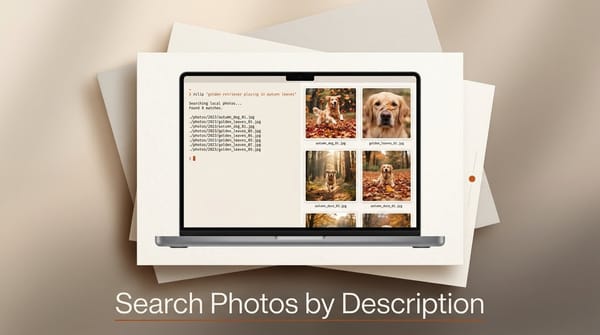
You can search a folder of photos by typing what is in them, offline and for free, with rclip. We indexed 1,000 photos in 12.8 seconds on a CPU; a one-sentence description put the right photo in the top 10 91.5% of the time.
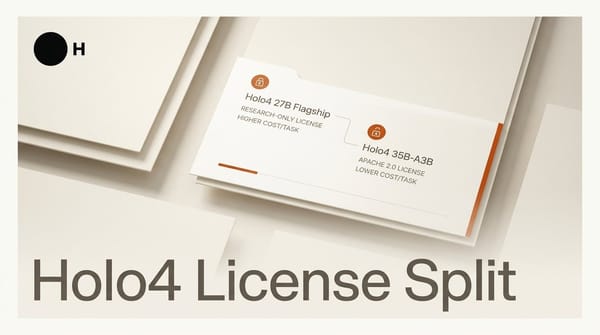
H Company's Holo4 ships two open-weight computer-use models. The 27B wins on long workflows at $2.94 per completed task but is research-only; the Apache 2.0 35B-A3B is the one you can self-host commercially.
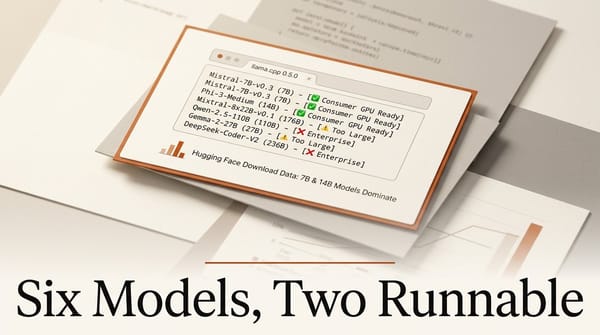
llama.cpp 0.5.0 shipped on 23 September 2026 with six new model families in its release notes. The download and file-size data on Hugging Face tells a narrower story about which of them you can actually run tonight.
Google's Antigravity SDK now runs agents on local models: Gemma 4 26B A4B through LiteRT-LM, or any OpenAI-compatible server such as Ollama, LM Studio or vLLM. We read the SDK source and the demo code behind its 97.2% local-token headline.
ComfyUI cut a MiniMax H3 encode and decode round trip from 24.3 to 12.7 seconds. Only one of the three changes is on by default. The other two need a launch flag and a file download.
Hugging Face shipped direct GGUF support in Transformers on 22 September 2026. The benchmarks show near-parity with llama.cpp, but a footnote under the chart and four hard constraints decide whether it is usable for you today.
Ant Group's inclusionAI released Ming-Image-0.1-Design under MIT: top of the open-weights UI/UX design leaderboard at 1082 Elo, with native RGBA output and a companion model that splits a finished design back into editable layers. The 6B label describes one component of a 52.88 GB package.
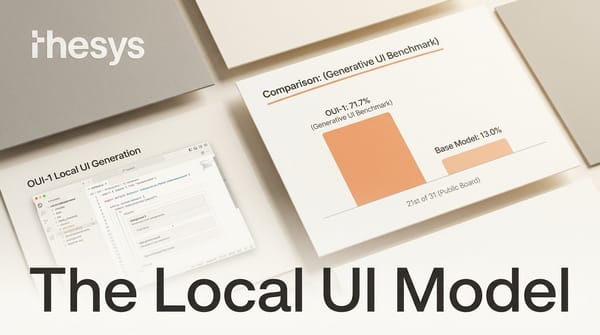
Thesys shipped OUI-1 on 8 September 2026, the first model built specifically to generate user interfaces. It scores 71.7% on the Generative UI Benchmark against its base model 13.0%, and twenty-first of thirty-one on the same public board.
On September 8, 2026, European lab Desert Ant Labs published 18 small AI models that run entirely on a users device, with SDKs for Swift, Kotlin and JavaScript and a free tier covering the first 100,000 monthly active devices per platform.
OpenBMB released MiniCPM5-2B on September 7, 2026, a 2.6B dense Apache-2.0 model that Artificial Analysis ranks #1 of 47 open-weights models at or under 4B parameters. The Q4_K_M quantization is 1.56 GB on disk.
llama.cpp shipped version 0.4.0 on September 4, adding initial support for Qwen3.8-Flash-Next, NVIDIA Nemotron-3-Puzzle-75B-A9B, and video input for local multimodal models.
Microsoft announced Project Zenith on September 4, 2026: a ready-to-code Windows 11 experience gated behind 64 GB of unified memory and 250 GB/s of bandwidth, so developers can run 30B+ models locally and unmetered.
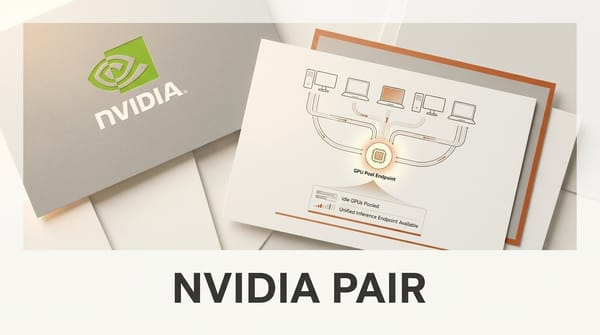
NVIDIA PAIR is a free, open-source Personal AI Router that turns the idle GPUs across your home or studio into one local inference endpoint. Here is how it works and when it beats the cloud.
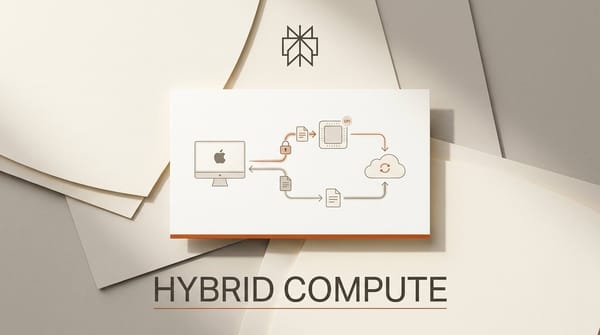
Perplexity launched Hybrid Compute for its Computer agent on Apple silicon Macs, splitting a single task between cloud and local models so confidential files never leave the device.
Apple unveiled the M6 and M5 Ultra chips on August 25, 2026, and the headline is on-device AI: the M5 Ultra can run and fine-tune 100B-plus parameter models entirely on a Mac.
Unsloth AI released Unsloth Desktop, a free open-source app that runs and fine-tunes LLMs and diffusion models locally, 2x faster with 70 percent less VRAM.
Liquid AI released LFM2.5-2.6B, a 2.6-billion-parameter open-weights agentic model that runs entirely on-device, planning and calling tools with no cloud API cost.