Vannarot Roeung
Recent posts by Vannarot Roeung
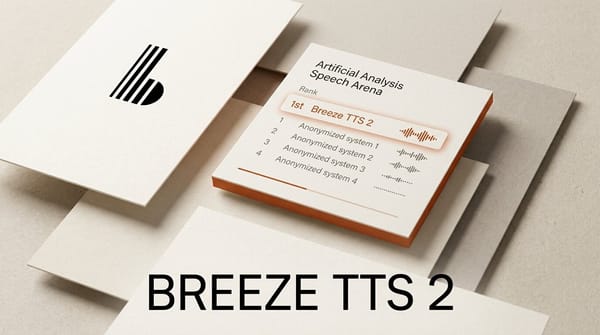
Breeze TTS 2 Tops Open-Weights TTS Leaderboard
BreezeBlue has open-sourced Breeze TTS 2, a text-to-speech model that now ranks first among open-weights systems on the Artificial Analysis Speech Arena.
MiniMax H3 Max: Free Fast AI Video From fal
Fal has released MiniMax H3 Max, a post-trained version of MiniMax H3 tuned for speed: 5-second 768p clips with synced audio in under three seconds.
IBM Granite 4.2: Open Agentic Coding Models
IBM shipped Granite 4.2 on August 25, 2026, a family of open, Apache 2.0 licensed agentic coding models in 3B, 8B, and 30B sizes that you can download and self-host today.
Claude Unifies Memory Across Chat and Cowork
Anthropic unified Claude's memory across Chat and Cowork so context carries between both surfaces, on by default across Free, Pro, and Max, with per-topic controls and sensitive-topic exclusions.
Apple M6 and M5 Ultra Supercharge Local AI on Mac
Apple unveiled the M6 and M5 Ultra chips on August 25, 2026, and the headline is on-device AI: the M5 Ultra can run and fine-tune 100B-plus parameter models entirely on a Mac.
Wan 3.0 in ComfyUI: Native 30-Second AI Video
Alibaba's Wan 3.0 video model is now available natively inside ComfyUI with single-pass 30-second generation, up to 1080p output, and a 20-asset Omni-Reference system.
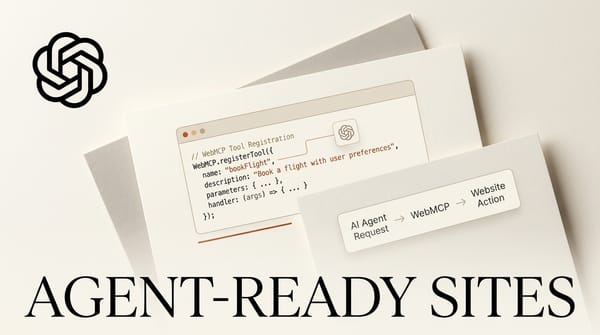
How to Make Your Site Agent-Ready With WebMCP
WebMCP lets your site hand AI agents named actions to call instead of scraping HTML. Here is how to expose your first WebMCP tool in about 30 minutes.
How to Turn a Blog Post Into a Video With AI
Turning a blog post into a video used to take days. In 2026 one person can do it in about an hour with four AI tools: an LLM to script, a voice generator, a text-to-video tool, and a free editor.
Persistent vs Reactive AI Agents: Headlong Explained
Headlong is an open-source microharness that keeps an AI agent thinking in a continuous self-guided loop instead of freezing between tasks, built by the Laude Institute and MIT in under 10,000 lines of Bash.
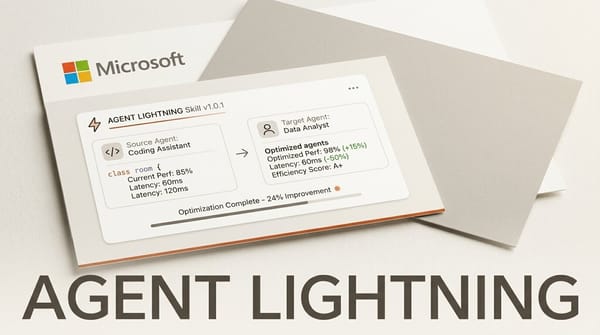
Agent Lightning Skill: Auto-Optimize Your AI Agents
Microsoft has shipped the first official release of the Agent Lightning Skill (v1.0.1), a drop-in tool that lets a coding agent automatically optimize other AI agents.
Construct Computer Gives AI Agents a Cloud Desktop
Construct Computer launched August 23 as an AI employee platform that gives each agent its own persistent cloud desktop to run workflows, build internal tools, and file research.
FetchSandbox MCP Tests AI Agent API Integrations
FetchSandbox launched August 23 as a sandbox for testing the API integrations your AI coding agent writes, without touching real services or spending real credentials.
NewFace.AI Launches for E-Commerce and UGC Video
LibAI Lab has launched NewFace.AI, an AI image and video platform for e-commerce sellers, agencies, and UGC creators, pairing a natural-language agent with a visual canvas.
GitHub Copilot Agents Come to Teams and Slack
GitHub shipped Copilot agentic coding sessions into Microsoft Teams and Slack on August 21, 2026, letting teams direct and review an agent from chat.
DeepSeek V4-Flash Adds Vision at No Price Premium
DeepSeek added image understanding to its cheapest fast model on August 21, 2026, billing images at standard V4-Flash rates with a free Files API.
Frontier AI API Prices Dropped: What It Costs Now
OpenAI cut developer pricing for GPT-5.6 Sol on August 21, 2026. Input fell from $5 to $4 per million tokens and output from $30 to $20, putting it below Claude Opus 5 on both sides.
Qwen3.8-27B Now Runs Locally on 8GB of RAM
On August 20, 2026, Unsloth shipped a full Dynamic V3.0 GGUF release for Qwen3.8-27B, including a 1-bit quantization that runs in roughly 8GB of RAM. The 27B model that needed about 56GB at full precision now fits on hardware most creators already own.
ChatGPT Search Now Leans on the site: Operator
ChatGPT Search started using the site: operator at scale on August 8, 2026. Usage in fan-out queries jumped from 0.3-0.5 percent to 16 or 17 percent overnight.
Google Antigravity Lands in VS Code, JetBrains, Zed
Google shipped Antigravity IDE extensions on August 20, 2026, bringing its agentic coding tool into VS Code, Visual Studio 2026, JetBrains, and Zed.
ElevenLabs Retires Its Local MCP Server
ElevenLabs archived its local MCP server repository on August 20, 2026, pointing developers to a hosted server that authenticates with OAuth rather than a copied API key.
ChatGPT Adds an Apple Messages Plug-in on Mac
OpenAI shipped an Apple Messages plug-in for the ChatGPT desktop app on August 20, 2026. It reads iMessage, SMS, and RCS conversations locally and drafts replies.
Google Preferred Sources Button Lands for Publishers
Google released an embeddable Preferred Sources button for publishers on August 20, 2026. Readers click it to mark you as a preferred source across Search, Discover, and Google News.
Slack Code Puts AI Agents in Shared Team Channels
Slack shipped Slack Code on August 20, 2026, a channel type where a team and its AI coding agents work in the same shared thread.
ComfyUI v0.33.3 Adds Seedance, FishAudio, Flux Nodes
ComfyUI tagged v0.33.3 on August 20, 2026, closing a two-release window that added five new partner integrations in four days.