Mercury 2.5 Preview: Fast, Cheap Diffusion LLM
Inception released Mercury 2.5 Preview on August 31, 2026, a diffusion LLM that generates tokens in parallel, hitting up to 1,107 tokens per second at cost-optimized pricing on OpenRouter.
Inception released Mercury 2.5 Preview on August 31, 2026, a diffusion LLM that generates tokens in parallel, hitting up to 1,107 tokens per second at cost-optimized pricing on OpenRouter.
Tencent has open-sourced Hy4 preview, a 770B mixture-of-experts model with a 1M-token context window under Apache 2.0, aimed at coding, data analysis, and builder workflows.
Z.ai officially launched GLM-5.3-Flash, the stealth Ox Alpha model that topped OpenRouter, as an MIT-licensed open-weight coding model.
Alibaba released Qwen3.8-Flash-Next as open weights on Hugging Face and ModelScope, the first public preview of its next-generation Qwen4 architecture.
OpenAI cut developer pricing for GPT-5.6 Sol on August 21, 2026. Input fell from $5 to $4 per million tokens and output from $30 to $20, putting it below Claude Opus 5 on both sides.
DeepSeek pushed its flagship V4 Pro to general availability on August 12, 2026, ending a preview that ran nearly four months. The GA build is a 1.6 trillion parameter MoE with a 1M-token context window.

Grok 4.6 hits 61 on the Artificial Analysis Intelligence Index at $2/$6 pricing and finishes agent tasks in roughly half the turns of premium rivals. Full benchmarks and a creator workflow.
OpenAI launched a ChatGPT desktop app for Linux on August 11, 2026, bringing ChatGPT, Work, and the Codex coding agent to Ubuntu, Debian, and Fedora.
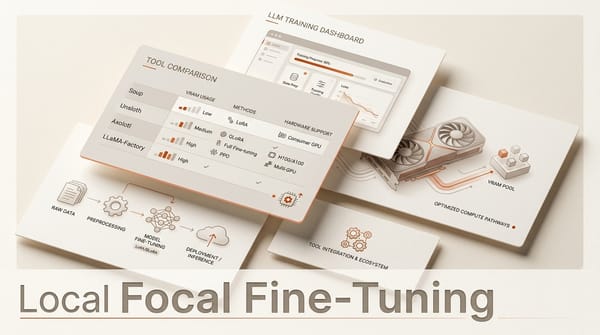
Which local fine-tuning tool should you install? Soup, Unsloth, Axolotl, and LLaMA-Factory compared on the constraints that actually decide it.
OpenAI gave free ChatGPT users unlimited text chats and moved them to GPT-5.6 Luna, while Plus and Pro get the Sol flagship and a new thinking slider.
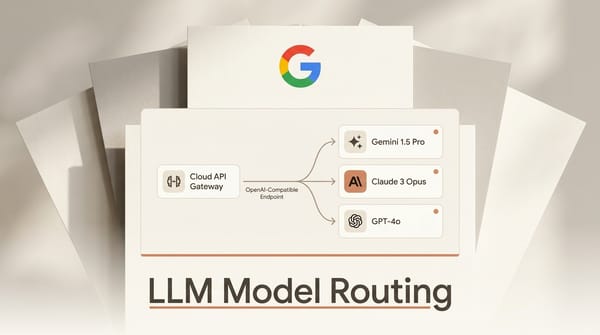
Google shipped model routing for Cloud API Gateway on August 4, 2026: one OpenAI-compatible endpoint that forwards each request to Gemini, Claude, or an OpenAI GPT model.
Cloudflare shipped three inference optimizations that make Kimi K2.6 and GLM 5.2 roughly 30% cheaper to run on Workers AI, and its benchmark tables show the answers do not change.
Alibaba announced Qwen3.8-Max on August 3, 2026: a 2.4 trillion-parameter coding flagship with a 1 million-token context and a promised open-weights release.
DeepSeek shipped the official production build of V4 Flash on July 31, 2026: an open-weight, MIT-licensed 284B-parameter MoE model with a 1M token context, native OpenAI Responses API and Codex support, and API output at $0.28 per million tokens.
Thinking Machines released Inkling-Small on July 30, a 276B open-weight MoE with 12B active params that matches or beats the full Inkling on reasoning and coding at a third the token price.
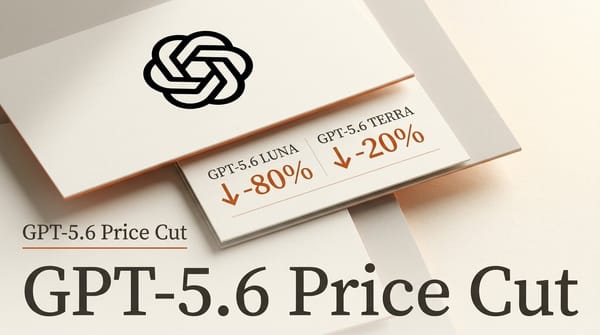
OpenAI cut API prices on its two cheaper GPT-5.6 tiers on July 30, 2026, dropping Luna 80% and Terra 20% while leaving the top Sol tier unchanged.
TurboFieldfare is an open-source Swift and Metal engine that runs Google Gemma 4 26B in about 2GB of RAM on any M-series Mac by streaming experts from SSD.
OpenAI's GPT-5.6 family is now on Amazon Bedrock, giving builders three model tiers, Sol, Terra, and Luna, inside the AWS stack they already use.
Claude Opus 5 launched July 24, 2026 at the same $5/$25 pricing as Opus 4.8, but Anthropic says it more than doubles 4.8's performance and undercuts Fable 5 on cost per completed task.
Echo, a new public-alpha endpoint from Tracer, pools open-weight models like GLM-5.2 and Kimi behind one OpenAI-compatible API, promising Claude-class output at roughly a third of the cost.
NvChat is a free, open-source Windows app that gives you a native desktop chat interface for NVIDIA free hosted LLM API, with access to more than 100 models including vision and reasoning models.
Anthropic updated Claude voice mode to run on Opus and Sonnet, not just Haiku, and to act inside Gmail, Calendar, Slack, Canva, and Notion by voice. Here is what changed and how to use it.
Upstage released Solar Open 2, a 250-billion-parameter open-weight MoE built for long-horizon agentic coding, tool calling, and document work.
Alibaba's Qwen team announced Qwen3.8, its next flagship model, saying it will go open-weight soon. As of July 19, 2026 there are no weights or benchmarks yet.