Deep Dive
Oct 7, 2026
Claude Haiku 5.5 launched October 7 at $0.10 in and $0.50 out per million tokens, 90% under Haiku 4.5 for most jobs. Here is what that means per podcast show note, caption and browser chore, and when to pick Sonnet 5.5 instead.
Deep Dive
Oct 6, 2026
OpenAI opened the Decisions API to every developer on 6 October 2026: gpt-6-luna returns probabilities, choices and rubric scores at $0.10 per 1M input tokens, with no output charge. We compared it with the Responses API, Cloudflare Clef and TypeSafe Jev.
Deep Dive
Oct 6, 2026
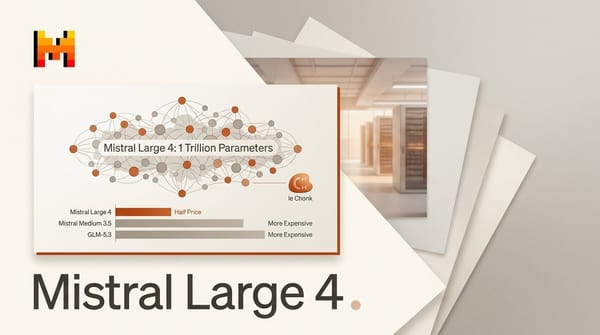
Mistral Large 4, a 1-trillion-parameter open-weight model, entered public preview on October 6, 2026 at $0.68 input and $2.09 output per million tokens, half its list price. It costs less than Mistral Medium 3.5 and GLM-5.3. Weights are due at the end of October.
Deep Dive
Oct 1, 2026
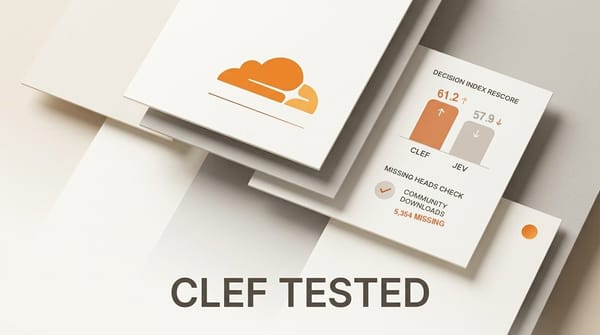
Cloudflare's open Clef decision models would top the Decision Index at 61.2 on Cloudflare's own numbers, but cost 5.7 times Jev per token, Clef-flash fails hallucination checks, and 5,354 downloads went to GGUF files missing the decision head.
Deep Dive
Sep 29, 2026
OpenAI's GPT-6.1 Sol costs the same per token as GPT-6 Sol with cached input halved. We pulled the 102 points behind OpenAI's charts: High beats Astra on DeepSWE, Max scores lower at 2.4x the cost, and Opus 5.5 still leads AutomationBench.
Deep Dive
Sep 28, 2026
Claude Sonnet 5.5 costs half of Opus 5.5 per token and beats it on Terminal-Bench 4.0. At max effort, Artificial Analysis measured $7.60 per task against Opus 5.5's $5.98. Here is how effort decides your bill, and the five breaking changes to fix first.
Deep Dive
Sep 22, 2026
Anthropic cut Opus pricing 20% and took the number one spot on the Artificial Analysis index. The line that will actually change your bill is the effort default, which dropped from high to medium.
Deep Dive
Sep 21, 2026
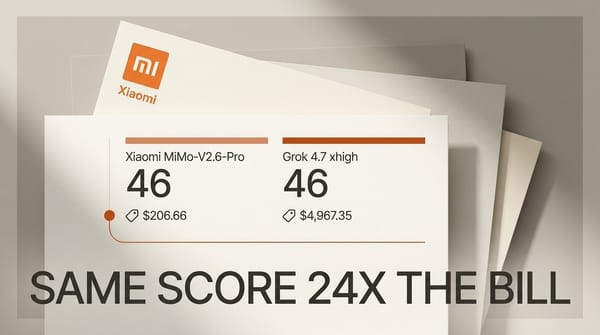
Xiaomi open-sourced MiMo-V2.6-Pro under MIT on 21 September and it scored 46 on the Artificial Analysis Intelligence Index. Grok 4.7 launched the same day and scored 46 too. Running that identical evaluation cost $206.66 on one and $4,967.35 on the other.
Deep Dive
Sep 20, 2026
Altworld released Hemmingway-1 on 20 September: 27B parameters, Apache-2.0 weights, fine-tuned from Qwen3.8-27B. It tops two of its own benchmarks, places third on the one it does not own, and comes last of seven on both story columns. The numbers were published only inside chart images.
Deep Dive
Sep 19, 2026
TypeSafe opened access to Jev on 15 September. Within 48 hours six open reproductions had shipped, each claiming to match it. Four independent evaluations put Jev's own Banking77 accuracy at 87.0%, 83.2%, 77.8% and 76.3%.
Deep Dive
Sep 14, 2026
When Suno shipped v6, every older model left the picker the same day. Amazon Bedrock gives most models six months. The length of the warning you get is set by the platform you call the model through, not by the model.
Deep Dive
Sep 11, 2026
Agnes AI published Agnes-3.0-Flash Preview, a 33B hybrid-attention multimodal model with a 262,144-token context window, under Apache 2.0 on 11 September 2026. The downloadable weights are a different checkpoint from the Agnes 3.0 Flash listed on Artificial Analysis.
Deep Dive
Sep 10, 2026
Cohere released North Small Translate 1.0 on 10 September 2026, a 218B model scoring 83.60 on WMT26 against DeepL NextGen at 81.37. The weights are CC BY-NC 4.0, so you cannot use them in anything you sell.

Deep Dive
Sep 9, 2026
DeepSeek shipped V4.1-Flash on 10 September: 552B multimodal MoE, MIT open weights, cache-hit prices down 57%, and every V4-Pro API call rerouted to it from 14 September.
Deep Dive
Sep 7, 2026
OpenBMB released MiniCPM5-2B on September 7, 2026, a 2.6B dense Apache-2.0 model that Artificial Analysis ranks #1 of 47 open-weights models at or under 4B parameters. The Q4_K_M quantization is 1.56 GB on disk.
AI
Sep 4, 2026
H Company released NeoMME, an Apache 2.0 family of multimodal and multilingual encoders for visual document retrieval and RAG, in 260M and 800M sizes.
LLM
Sep 3, 2026
OpenAI began rolling out GPT-6 Astra on September 3, its most capable model for computer use, browsing, and software engineering, with paid ChatGPT tiers and the API to follow in the coming days.
Deep Dive
Sep 3, 2026
Hugging Face's open-source Funes gives coding agents like Claude Code and Codex a persistent memory that lives on your machine and travels between tools. Here is how the agent-memory-you-own pattern compares to vendor-locked and knowledge-graph memory.
Open Source
Sep 3, 2026
IFM released K2 Horizon on September 3: six fully open models from 0.9B to 375B, shipped with weights, code, and training data under Apache 2.0. Here is how to download and run them.
Deep Dive
Sep 2, 2026
Anthropic open-sourced Claude Commerce Agents on September 2, 2026, a forkable blueprint for shopping and merchant agents. Here is the fork-to-shipped builder path, and how the open blueprint compares to a raw SDK build and closed vertical platforms.
Deep Dive
Sep 2, 2026
Meta shipped Muse Spark 1.3 with a pitch built on efficiency: roughly 20 percent fewer tool calls and 25 percent fewer tokens per coding task. Here is why tokens and tool calls per completed task, not raw benchmark score, are the metric that actually decides what an agent costs to run.
Deep Dive
Sep 1, 2026
Mercury 2.5 and Celeris-1 Magnus are diffusion LLMs that decode tokens in parallel to cut agent latency. Here is how they compare and when to swap.
LLM
Sep 1, 2026
Celeris-1 Magnus is a hybrid diffusion language model built for agentic work that the startup says runs faster than autoregressive models on tool-heavy tasks. It exposes an OpenAI-compatible API available today.
Deep Dive
Sep 1, 2026
Anthropic released Claude Fable 5.1 on September 1, 2026. Headline pricing did not move, but cache reads dropped from $1.00 to $0.25 per million tokens, a 75 percent cut worth up to 45 percent on agentic workloads.