Vannarot Roeung
Recent posts by Vannarot Roeung
ElevenLabs Launches ElevenMusic App for AI Song Creation
ElevenLabs launched ElevenMusic, a free iOS app that lets users create and remix songs using text prompts. The app marks the company expansion from voice AI into music generation.
Gemma 4 Rewrites the Open Source AI Playbook
Google released Gemma 4, a family of four open multimodal models under Apache 2.0. The 31B dense model scores 89.2% on AIME 2026, quadrupling Gemma 3. For creators and developers building on open models, this changes everything.
Microsoft Launches 3 In-House AI Models, Reducing OpenAI Dependence
Microsoft launched three in-house AI models on April 2, reducing its dependence on OpenAI. MAI-Image-2, MAI-Voice-1, and MAI-Transcribe-1 cover image generation, text-to-speech, and speech recognition.
Alibaba Qwen3.6-Plus Turns Wireframes Into Code
Alibaba releases Qwen3.6-Plus with 1M-token context, autonomous repository-level coding, and the ability to convert wireframes and screenshots directly into working frontend code.
GitHub Copilot /fleet Runs Multiple AI Agents in Parallel
GitHub launches /fleet in Copilot CLI, dispatching multiple AI agents to work on different tasks simultaneously instead of processing requests sequentially.
Liquid AI LFM2.5-350M Runs AI Agents in 81MB on Mobile
Liquid AI releases LFM2.5-350M, a 350M parameter open-weight model that runs AI agents on mobile GPUs in just 81MB with 32k context window.
GLM-5V-Turbo Scores 94.8 on Design-to-Code
Z.ai launches GLM-5V-Turbo, a vision-coding model that scored 94.8 on Design2Code versus 77.3 for Claude Opus 4.6. Converts mockups directly to frontend code.
OmniVoice: Open Source TTS Covers 600 Languages
OmniVoice is a zero-shot text-to-speech model supporting 600+ languages with voice cloning, an Apache 2.0 license, and inference 40x faster than real-time.
Alibaba Wan2.7-Image Unifies AI Generation and Editing
Alibaba released Wan2.7-Image, a unified AI model that handles both image generation and editing in one system, with fine-grained personalization, color control, and a Pro variant capable of 4K output.
Arcee Ships Open Reasoning Model at 96% Less Cost
Arcee AI releases Trinity-Large-Thinking under Apache 2.0, ranking #2 on PinchBench behind Claude Opus 4.6 at just $0.90 per million output tokens.
PrismML Open-Sources Bonsai 8B: A True 1-Bit LLM
PrismML emerged from stealth and open-sourced Bonsai 8B, a true 1-bit large language model that fits 8.2 billion parameters into just 1.15 GB of memory, roughly 14x more compressed than comparable 16-bit models.
Falcon Perception: 0.6B Vision Model Beats Meta SAM 3
Technology Innovation Institute releases Falcon Perception, a compact 0.6B parameter vision model that beats Meta SAM 3 across six key benchmarks while running on consumer hardware.
Google Veo 3.1 Lite Cuts AI Video Costs in Half
Google launches Veo 3.1 Lite, a cost-effective video generation model available now via the Gemini API and Google AI Studio.
H Company Holo3 Sets New SOTA for GUI Agents
H Company released Holo3, a vision-language model optimized for GUI agents that sets new state-of-the-art on the OSWorld-Verified benchmark, beating proprietary models with only 3B active parameters.
The Anti-Slop Movement Is Reshaping Creative AI
A viral browser game called Your AI Slop Bores Me hit 50 million views in its first week. The anti-slop movement is reshaping how creators, brands, and platforms think about AI in creative work.
Claude Code Source Leak: 500K Lines Exposed via npm
Anthropic accidentally exposed the full source code of Claude Code on March 31, leaking roughly 1,900 files and over 500,000 lines of TypeScript through an npm packaging error.
Runway Bets on Ecosystem Over Product at AI Summit
One week after OpenAI killed Sora, Runway launched a $10M venture fund and Builders program at its first AI Summit. The company is building a platform for AI video, not just a tool.
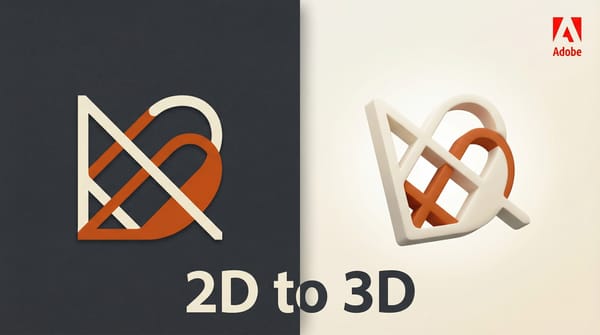
Adobe Illustrator Turntable Turns 2D Vectors Into 3D
Adobe Illustrator Turntable is now generally available, automatically generating up to 74 editable 3D views from a single 2D vector.
Qwen3.5-Omni Handles Text, Image, Audio, Video in One Model
Alibaba releases Qwen3.5-Omni, a multimodal AI model that processes text, images, audio, and video while generating real-time speech output in 36 languages.
Mistral Bets $830M on European AI Sovereignty
Mistral raises $830M in debt financing to build a Paris data center with 13,800 NVIDIA GB300 GPUs. Why Europe's biggest sovereign AI infrastructure play matters for creative professionals.
Skywork Matrix-Game-3.0: Open-Source Real-Time Video AI
Skywork AI releases Matrix-Game-3.0, an open-source model that generates real-time interactive video at 720p and 40fps.
Apple LGTM Brings 4K 3D Scene Rendering Without Per-Scene Training
Apple researchers published LGTM on March 28, 2026, a method that enables 4K-resolution 3D scene rendering using Gaussian Splatting without requiring per-scene optimization.
Claude Paid Subscriptions More Than Double in 2026
Anthropic confirmed that Claude paid subscriptions have more than doubled in 2026, with credit card data showing record subscriber growth in January and February.
NVIDIA Kimodo: Open-Source Motion AI for 3D
NVIDIA has open-sourced Kimodo, the largest controllable motion diffusion model ever trained. Trained on over 700 hours of professional motion capture data, it generates 3D human and robot motions from text prompts.