Deep Dive
Oct 5, 2026
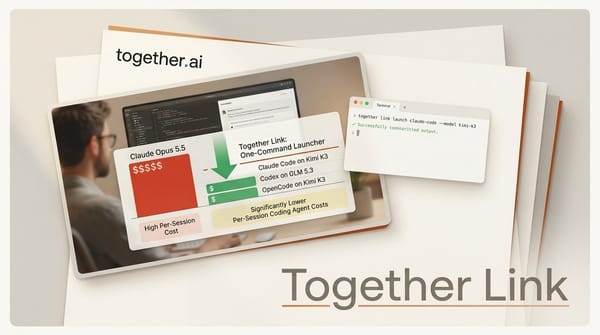
Together Link puts Kimi K3, GLM 5.3 and the Flash models inside Claude Code, Codex and OpenCode. Priced on 13 real Opus 5.5 sessions, the Flash models save 92-96%, but Kimi K3 saves only 6% because cache reads decide the bill.
Deep Dive
Sep 30, 2026
DeepSeek Harness Desktop, a free MIT agent app for Mac and Windows, sends a structured session log with every request on DeepSeek's own model route by default. Our capture test shows what it carries, what it costs, and how to switch it off.
Deep Dive
Sep 29, 2026
Sign in with ChatGPT now lets Plus and Pro subscribers spend their plan in other apps, with no API key. We checked the 4 open-source tools OpenAI lists on launch day: only Pi shipped it in a stable release, and the route refuses image generation.
Deep Dive
Sep 28, 2026
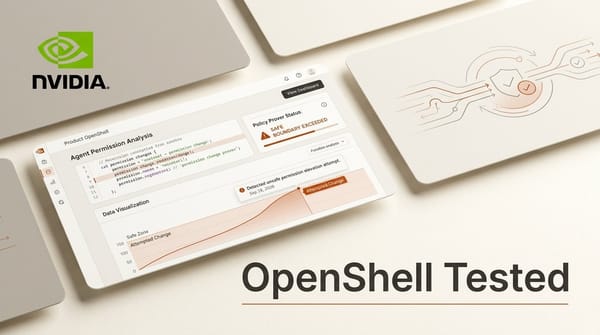
NVIDIA's Open Agent Safety Platform launched September 28, and OpenShell is the part you can run today. We gave its policy prover 19 permission-widening edits: it caught 9, answered unsupported on 9, and passed 1 the runtime blocks anyway.
Deep Dive
Sep 28, 2026
Claude Sonnet 5.5 costs half of Opus 5.5 per token and beats it on Terminal-Bench 4.0. At max effort, Artificial Analysis measured $7.60 per task against Opus 5.5's $5.98. Here is how effort decides your bill, and the five breaking changes to fix first.
Deep Dive
Sep 25, 2026
Ollaya, the open-source runtime that serves Jev-style decision models locally, hit the Hacker News front page on 25 September. We ran three of its models on a CPU against 300 labelled examples: Laya is fastest and most overconfident, decider:0.8b the most accurate.
Deep Dive
Sep 25, 2026
Meituan's LongCat-2.5-Preview landed on 25 September with a 1M-token context, image and video input, and a free OpenCode tier. It costs $0.30 in and $1.20 out per million tokens direct, but Meituan has published no benchmarks yet.
Deep Dive
Sep 24, 2026
Whiteboard, an open-source app from the YC W26 startup /dev/fast, shipped on 24 September. Claude Code and Codex can draw diagrams, semantic diffs and decision logs that link back to the code. Here is how to set it up, and what leaves your machine.
Deep Dive
Sep 24, 2026
Docker Cloud Sandboxes launched on 24 September at $0.14 an hour for 2 vCPUs, the lowest flat rate against E2B, Daytona and Modal. But Docker bills idle time, and coding agents spend much of theirs waiting on the model.
Deep Dive
Sep 23, 2026
Anthropic made Claude Code cloud sessions generally available on September 23, with a one-time $100 credit on Pro and $250 on Max. The VM is free; the credit pays for model usage, and on Opus 5.5 it goes less far than it sounds.
Deep Dive
Sep 23, 2026
CLM-8B, an open decision model from Stanford and NVIDIA released on 23 September, scores candidate actions up to 9x faster than Jev. Its 81.6% DeepSWE result is 31 of 38 tasks. Here is how to run it as a verifier for your coding agent.
Deep Dive
Sep 22, 2026
Anthropic cut Opus pricing 20% and took the number one spot on the Artificial Analysis index. The line that will actually change your bill is the effort default, which dropped from high to medium.
Deep Dive
Sep 16, 2026
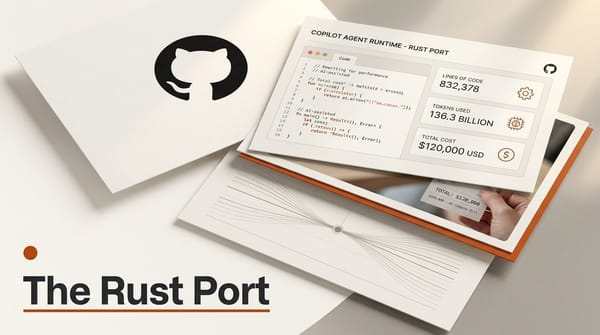
GitHub published the full telemetry for rewriting the Copilot agent runtime into 832,378 lines of Rust with AI agents: $120,000 in tokens, a 96.22% prompt cache hit rate, and 28 hours of reading for every hour of editing.
Deep Dive
Sep 12, 2026
Specific Labs published Real-SWE on September 12, 2026, a coding-agent benchmark built entirely from private production codebases. The top score is 38.8%, from Claude Fable 5.1 in Claude Code. The same generation posts 95% on SWE-bench Verified.

Deep Dive
Sep 10, 2026
Cognition released SWE-2 on 10 September 2026 and one number travelled: 50.0% on FrontierCode 1.1 Main, within a point of Fable 5.1, at 64% lower cost. Three rows below it, in the same table, is a number that did not.
Deep Dive
Jul 20, 2026
Hang4r is a free macOS app that runs Claude Code, Codex, and Cursor coding agents side by side, each isolated in its own git worktree with per-turn checkpoints and inline diff review.
Deep Dive
Jul 14, 2026
Juggler is a new open-source coding agent from JUCE creator Julian Storer that replaces the terminal with a visual, branching workbench for AI coding sessions.