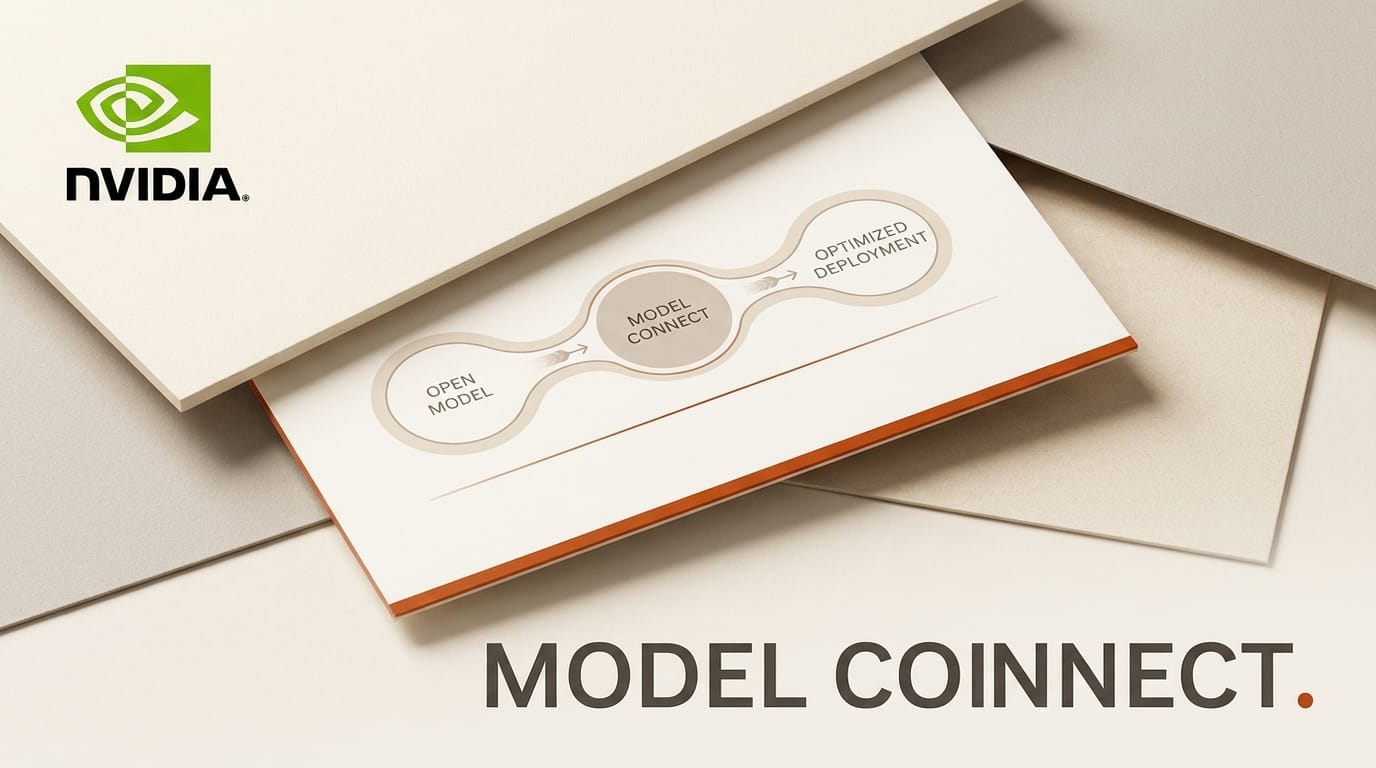
NVIDIA released TensorRT Model Connect on August 28, a free, open collection of reference implementations that takes an open-weights model from a raw checkpoint to optimized native inference in two commands. It handles the conversion, preprocessing, runtime, and postprocessing that usually block developers from serving open models in production.
What This Enables
If you have wanted to self-host an open model like Qwen 3 or Nemotron without wiring a Python inference server, this collapses the work to two steps. First you build a bundle with the Python CLI: trtmc build Qwen/Qwen3-0.6B -o qwen3-0.6B.bundle. Then a native C++ application loads that bundle and runs it with no PyTorch or Python at runtime. The bundle packs the TensorRT engines and model assets, so you ship one artifact and call trtmc::load to generate text. It is the fastest path yet from a Hugging Face checkpoint to a low-latency local endpoint you control. That means a creative app can call a fast local model for routine steps, such as captioning, tagging, or rewriting, and reserve a paid frontier API only for the hard requests, without you writing any deployment glue.
Why It Matters
Out-of-framework deployment has been the quiet bottleneck for open weights: export failures, missing operators, and hand-maintained plugins. TensorRT Model Connect removes the model-specific conversion code and the need for deep compiler expertise, and NVIDIA says it delivers performance competitive with or faster than torch.compile. For builders shipping products on open models, owning inference means no per-token platform fee and no vendor lock, built on TensorRT itself. It also pairs naturally with the open Nemotron line we covered in NVIDIA Nemotron 3.5 Lightning.
Key Details
Coverage: 80+ model families at launch, including Nemotron Speech and Qwen 3 VL, expanding through an agentic workflow.
Runtime: Native C++ with no Python dependency at inference time.
Hardware: Runs wherever TensorRT runs, including x86, ARM, DRIVE AGX, and Jetson AGX.
Cost: Free and open source, distributed as a GitHub project with nightly releases.
What to Do Next
Read the getting-started guide in the documentation, pick a small model like Qwen3-0.6B, and run the two-command build-and-load flow on a machine with an NVIDIA GPU. Then benchmark it against your current serving stack before you move a workload over.