Beyond LoRA: Hugging Face Tests Better Fine-Tuning Methods
Hugging Face benchmarked LoRA against newer PEFT methods like OFT, which beat it on image generation while using less memory. The default is not always the best fit.
Hugging Face benchmarked LoRA against newer PEFT methods like OFT, which beat it on image generation while using less memory. The default is not always the best fit.

A new open-source tool, UCP-Local, grounds Claude Desktop, Cursor, and LM Studio in your own files for fully offline retrieval. Released June 16, 2026 under Apache-2.0.
PixlStash, the open-source self-hosted image manager for AI creators, now ships as a native desktop app for Windows, macOS, and Linux with one-click install.

SlipMate is a free, open-source generative DJ instrument that runs two AI music models locally and lets you mix their output in real time like vinyl.
Zhipu has shipped GLM 5.2, a coding-first model now live across every tier of its Z.ai Coding Plan, led by a 1-million-token context window.
A new open-source Audio-Reactive LoRA for LTX 2.3 turns a still image and an audio track into a music-driven clip, with motion synced to the beat.

VibeClip is a new open-source, self-hosted tool that turns long videos into vertical captioned shorts you direct by chatting.
Moonshot released Kimi K2.7-Code on June 12, an open-weights coding model that beats Claude Opus 4.8 on MCPMark tool use at far lower cost.
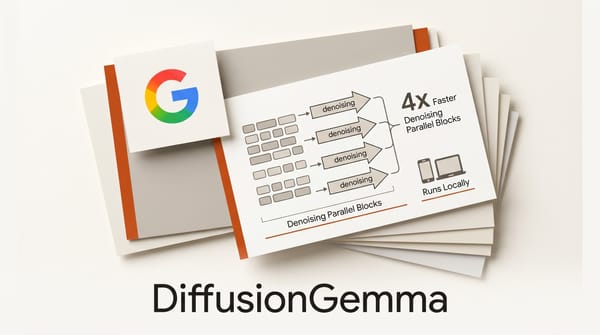
Google DeepMind released DiffusionGemma on June 10, 2026, an Apache 2.0 open model that generates text up to 4x faster by denoising blocks of tokens in parallel, and it runs on a single RTX GPU.
Xiaomi open-sourced MiMo Code, a free MIT-licensed terminal coding agent with persistent memory that runs on its MiMo-V2.5-Pro model and rivals Claude Code.
OpenCV 5.0 now runs LLMs, vision-language models, diffusion, and inpainting natively, turning the most-used vision library into a local runtime for an entire creative pipeline.
NVIDIA released Nemotron 3.5 ASR on June 4: an open 600M streaming speech model covering 40 language-locales with sub-100ms latency for voice agents.

Google AI Edge Gallery arrives on macOS with Gemma 4 12B support, bringing local AI model testing to Mac users for the first time.

Google's new Gemma 4 12B drops separate vision and audio encoders, packing native video and speech understanding into a single 12B open-weights model that runs locally.
Ideogram released its first open-weight text-to-image model on June 3, 2026: a 9.3B parameter Diffusion Transformer with JSON-structured prompting, in-image text rendering, and day-zero ComfyUI support.
TinyFish Bigset launched June 2 as an AGPL-3.0 open-source multi-agent system that turns a plain-English sentence into a structured dataset pulled from the live web, then refreshes it on a schedule.
NVIDIA forms Cosmos Coalition with Runway, Black Forest Labs, and LTX to build open video generation infrastructure.
JetBrains releases Mellum2 Thinking under Apache 2.0, an open-weights coding model with chain-of-thought reasoning.
Fizgig v1.2.4 makes full Flux 2 Klein 9B LoRA training possible on 16GB GPUs using fp8 Base DiT at 9.6GB VRAM. The free, open-source studio includes training presets, repair tools, and profiler.
NVIDIA pushed new PiD checkpoints June 2 with a FLUX.2 color-fix variant plus Qwen-Image support, all on Apache 2.0 for direct 4K decode in ComfyUI.

Deploy H Company's Apache 2.0 Holo 3.1 4B locally with vLLM on a 12GB consumer GPU, hook it into a desktop-agent workflow, and benchmark step latency and cost against Claude Computer Use and OpenAI Operator.
H Company released Holo 3.1, an Apache 2.0 computer-use agent family with quantized weights, mobile control, and 79.3% AndroidWorld score.
mistral.rs v0.8.2 delivers 3.5-5.5x faster MoE prefill on CUDA, fused decode kernels, and agentic tool-calling improvements for local LLM workflows.
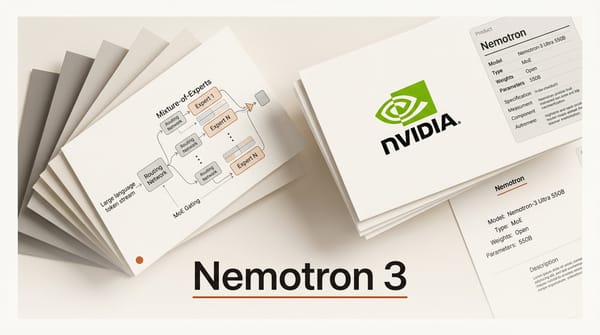
NVIDIA released Nemotron 3 Ultra on June 1 2026: a 550B mixture-of-experts model with 55B active parameters, open weights on Hugging Face, with 5x faster inference and 30% lower cost than Nemotron 2.