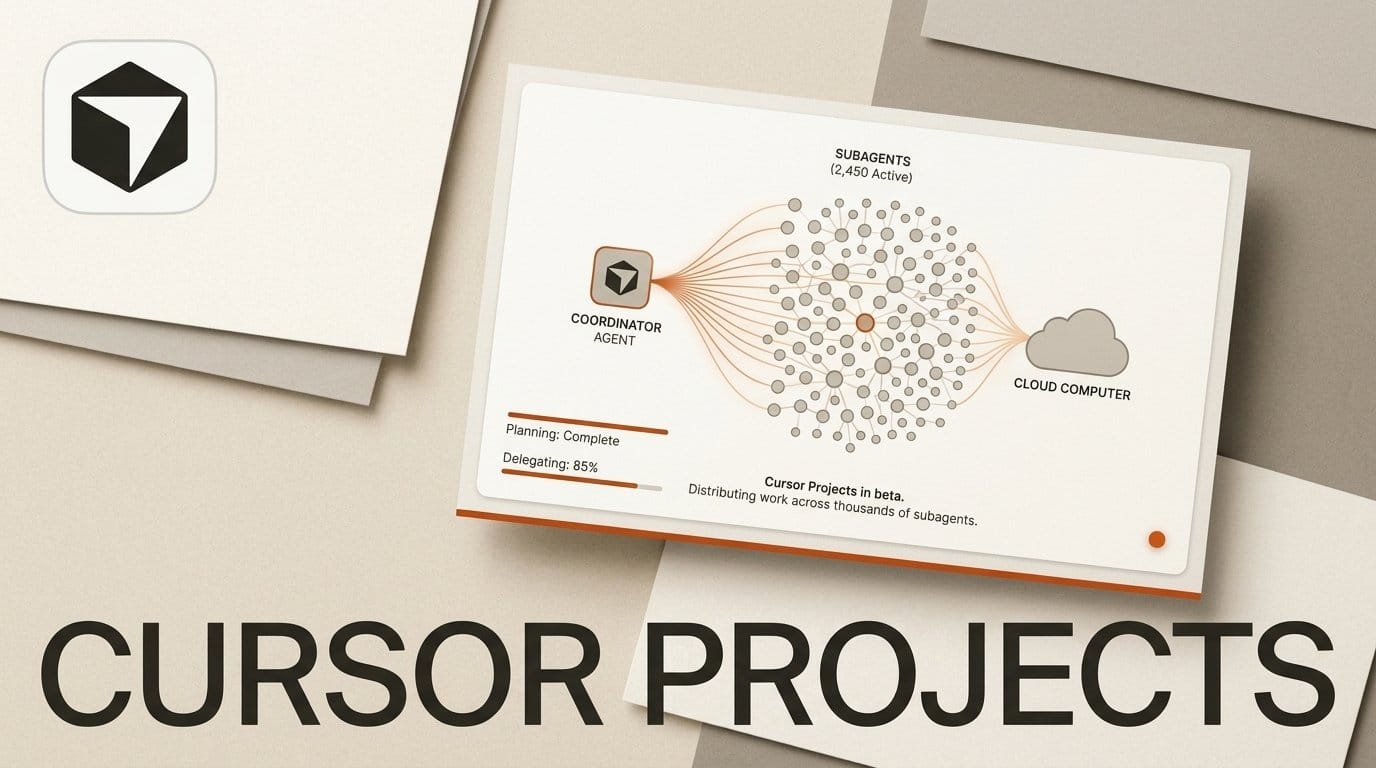
Cursor shipped Projects in beta on 10 September 2026. It adds a layer above the coding agent you already use: a coordinator agent that does not write code, plans the work, hands pieces to other agents, and brings the results back for you to check. The Project runs on its own computer in the cloud, so closing your laptop does not stop it.
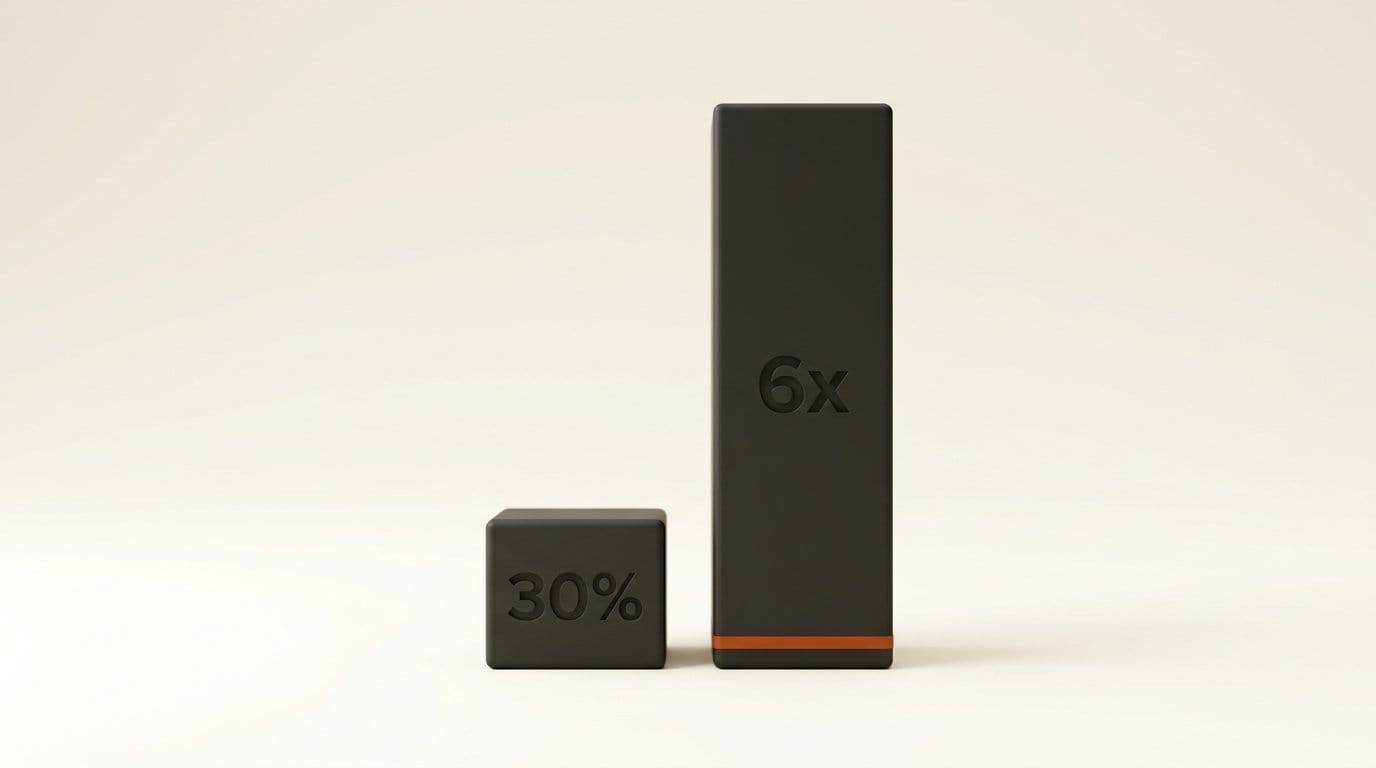
Cursor published two numbers with the launch. New Projects users merge 30% more pull requests. Users who make Projects their primary workflow merge six times as many.
Both numbers are real and neither one means what a headline will say it means. The six times figure describes who chooses to live inside Projects, not what Projects does to a typical engineer. And if agents genuinely open six times the pull requests, the scarce resource in your week stops being code and starts being review. That is the shift worth planning around, and it arrives with a second one that has had almost no coverage: a coordinator that watches a Slack channel and runs on a schedule spends money while you are asleep.
What Cursor actually shipped
Three pieces make Projects different from a longer chat thread.
A coordinator that delegates rather than codes. You talk to one agent in a thread that stays open for the life of the work, whether that is a feature, a migration across hundreds of pull requests, or ongoing maintenance. It plans, spawns implementing agents, and reports back. Cursor says a coordinator can direct thousands of subagents and stay responsive while they research, implement and test in parallel.
A cloud computer per Project. Each Project gets its own machine with files synced between cloud and local, so parallelism is not capped by your laptop and the work survives you shutting the lid. This is the same infrastructure line Cursor has been building all month: the 2 September changelog entry added self-hosted machines, letting cloud agent work run on your own infrastructure with dynamic pool scheduling.
Subscriptions. The coordinator can be told to watch a Slack channel, follow all your pull requests, or run on a schedule, and it delegates each time a matching signal arrives. Cursor lists fixing CI on a followed PR and picking up bug reports from Slack as examples. This is the part that changes the product category. Everything before it was a tool you invoked. This is a process you leave running.
It is rolling out in beta to all users through the left-hand navigation, per TestingCatalog's writeup. Cursor has not published a Projects documentation page yet, and the announcement names no plan requirement.
The two numbers, and what they do not say
Take the 30% first. That is the figure for new users, which is the honest one to quote, and it is a solid result if it holds outside Cursor's own telemetry. The company published no cohort size, no baseline and no time window, so it is directional rather than a benchmark.
The six times figure is the one that will travel, and it is a selection effect wearing a causal costume. The population it describes is people who tried Projects and then reorganised their working week around it. Those people were already running many agents, already had work shaped like a migration, and already had the review capacity to absorb the output. You cannot read a number drawn from that group as a forecast for an engineer who installs the beta on Monday. The gap between 30% and six times is mostly a gap between two kinds of user, not two kinds of outcome.
There is a more useful reading available. The gap tells you Projects rewards commitment and punishes dabbling. A coordinator that has been running for weeks has accumulated context about your codebase and your preferences; one you opened this morning has not. That is a real claim about the product, and it is testable in a way the six times is not.
Where Projects sits against the rest of the field
Four products shipped in the last six weeks that all claim to run coding agents over long horizons. They differ on the axis that actually matters for a bill: what happens when nobody is watching.
| Product | What coordinates the work | Where it runs | Acts on a trigger without you | How it is metered |
|---|---|---|---|---|
| Cursor Projects (beta, 10 Sep) | A coordinator agent that plans and delegates | A cloud computer per Project, or your own machines | Yes: Slack channels, PR follows, schedules | Subscription tier plus usage-based billing in arrears |
| OpenAI Agents API (public beta, 10 Sep) | Your code, calling the managed Codex harness | OpenAI-hosted sandboxes or your own | Only if you build the trigger | No API fee; tokens and tools only |
| Claude Managed Agents (beta) | Your code, calling a managed session | Anthropic-hosted sandbox | Only if you build the trigger | Tokens plus $0.08 per session-hour, idle time excluded |
| Herdr 0.9 | Nothing: it hosts the agents you already run | Your machines, one Rust binary | No | Free and open source; you pay your own model bills |
Read down the trigger column and the split is clean. OpenAI and Anthropic sell an engine and leave the ignition to you. Herdr, which we covered when 0.9 added multi-machine support, deliberately owns nothing above the terminal. Cursor is the only one of the four shipping the ignition, the schedule and the manager in one product, to everyone, in a beta with no opt-in ceremony.
That is a genuine product position rather than a feature gap, and it is consistent with where Cursor has been heading. We wrote about the same trajectory when cloud agents moved onto customer infrastructure and again in the comparison of the two managed agent APIs. Cursor is assembling a product for people who manage agents. The others are assembling parts for people who build with them.
The cost model changed and Cursor has not published a ceiling
This is the part of the launch with no coverage, and it is the part that will show up on a card.
Every prior version of this product charged you for attention you were paying. You typed, an agent ran, usage accrued, you watched the number. A subscription breaks that link. A coordinator following your pull requests fires when CI fails at 3am. A coordinator watching a Slack channel fires when someone reports a bug on Saturday. The work is delegated to subagents on a cloud machine, and the meter runs in both cases.
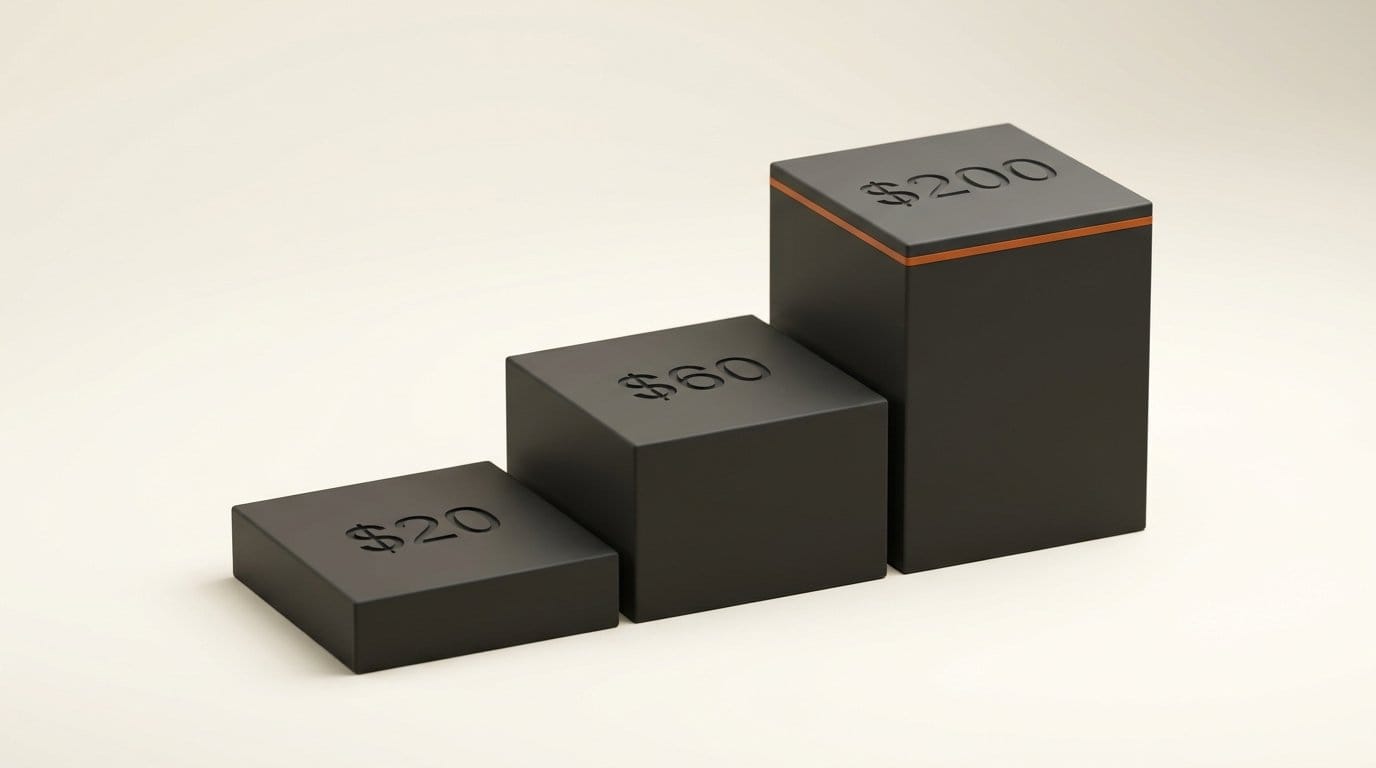
Cursor's published plans are Hobby at no cost, Pro at $20 per month, Pro+ at $60, and Ultra at $200, with 20% off annual billing. Cloud agents are included from Pro upward. Critically, all paid plans carry usage-based billing for overages, billed in arrears, and Cursor's own guidance has long put anyone running multiple agents in parallel at $200 a month or more. The announcement sets no cap on how many subagents a coordinator may spawn, names no plan floor for Projects, and does not say what happens when a scheduled subscription runs against an exhausted allowance.
Compare that to Anthropic's approach in the table above. Claude Managed Agents bills $0.08 per session-hour and explicitly does not charge for idle time, time spent waiting on your next message, or time after termination. That is a deliberate design choice about who absorbs the cost of an agent that is merely available. Cursor has made the opposite choice by making availability the product, and it has not yet said what that costs.
None of this makes Projects a bad deal. It makes it a deal you cannot price yet. If you turn on a subscription this week, set it to something with a bounded trigger rate, like your own pull requests, rather than an unbounded one like a busy Slack channel.
Nobody can benchmark the thing being sold
Here is the structural problem underneath every product in that table, and Projects makes it sharpest.
We can measure single-agent patch quality. SWE-bench and its descendants do exactly that, and Cognition's SWE-2 and its peers compete on those boards openly. What Projects sells is not patch quality. It is decomposition quality: the coordinator's judgment about how to split a migration into pieces, which pieces to run in parallel, when a subagent is stuck, and what to escalate. That is the hardest part of engineering management and there is no public benchmark for any of it.
So the only evidence available for the claim at the centre of this product is a vendor-reported merge count. Merged pull requests measure throughput, not correctness, not maintainability, and certainly not whether the decomposition was right. A coordinator that splits one coherent change into eleven pull requests will score extremely well on that metric and leave a worse codebase behind.
This is why the review bottleneck matters more than it sounds. Six times the pull requests against unchanged human review capacity does not produce six times the shipped value. It produces a queue, and eventually it produces rubber-stamping, which is the failure mode that turns an agent fleet into technical debt at speed. We made a version of this argument when comparing Spotify Xirp against Conductor and Vibe Kanban, and Projects raises the stakes because the coordinator now decides how many reviews you get.
Who should turn this on this week
Projects earns its keep on work with a specific shape: large, repetitive, mechanically verifiable, and boring. A framework version bump across hundreds of files. A lint rule rolled out repository-wide. A dependency migration with a test suite that actually catches regressions.
It earns nothing on work that is small, novel, or where correctness is a judgment call. A coordinator cannot tell you that the feature was the wrong feature, and delegating an ambiguous task to twelve agents produces twelve confident interpretations of your ambiguity.
If you are going to test it, do the sequence in this order. Pick one migration you have been avoiding, where a green test suite is a genuine proof of correctness. Run it as a single Project with no subscription attached, so the only compute you spend is compute you asked for. Measure the review time it generates, not the pull requests it opens. Then, and only then, decide whether a scheduled subscription is worth pointing at a trigger you control.
Frequently asked questions
Do I need a specific Cursor plan for Projects?
Cursor has not said. The announcement describes a beta rolling out to all users and names no plan requirement, while the pricing page lists cloud agents as a Pro, Pro+ and Ultra feature and does not mention Projects at all. Because Projects runs subagents on cloud machines, assume it consumes the same usage pools cloud agents do, and check your billing page after the first run rather than after the first month.
What does a coordinator agent actually do differently?
It does not write code. It holds the plan, splits work into tasks, spawns implementing agents for each, tracks which are blocked, and returns finished work to you. The practical difference from a long chat is persistence and parallelism: the thread outlives your session, and the agents under it run at the same time rather than one after another.
Is 30% more pull requests a trustworthy number?
It is the more trustworthy of the two Cursor published, because it describes new users rather than committed ones. Treat it as directional. Cursor disclosed no cohort size, no baseline and no measurement window, and pull requests merged is a throughput measure that says nothing about whether the changes were correct or well scoped.
How is this different from the OpenAI Agents API?
The Agents API gives developers the Codex harness behind one call, with durable sessions, streaming and your own tools or MCP servers, and charges only for tokens and tools. It is a building block. Projects is a finished product with a manager, a schedule and a user interface, aimed at someone who wants to direct agents rather than build a system that directs them.
Will this increase my bill even when I am not working?
If you attach a subscription, yes, by design. The feature exists so the coordinator can act on a schedule or a Slack message without you present, and delegated subagents run on metered cloud compute. Cursor has published no cap on subagent count and no guidance on what a running subscription costs per week. Start with a trigger whose rate you control.
Can I run this on my own infrastructure?
Cursor added self-hosted machines for cloud agent work on 2 September, with dynamic pool scheduling, so the underlying capability exists. The Projects announcement does not state whether a Project's own computer can be one of your machines. If that matters for your compliance posture, confirm it before running anything sensitive through a coordinator.
What should I measure to know if it worked?
Review hours per merged change, and the rate at which merged changes get reverted or patched within a week. Both are hostile to the throughput narrative, which is exactly why they are the useful ones. If review hours per change fall and the revert rate holds steady, the coordinator is decomposing work well. If pull requests rise and reverts rise with them, you have bought a queue.