Deep Dive
Oct 21, 2026
On October 21, 2026, HeyGen made HeyGen Voice Turbo free until November 30 and set its paid price at $4 per million characters. It now ranks first on the Artificial Analysis Controlled Voice leaderboard. Here is what a voiceover costs against ElevenLabs, and what the ranking does not prove.
Deep Dive
Oct 20, 2026
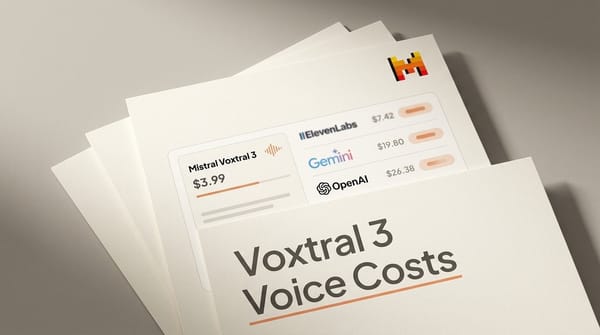
Mistral released Voxtral 3 on October 20, 2026: a $13 per million character voice model and transcribers from $0.0035 a minute. About 12 cents for a 10-minute voiceover, 21 cents for an hour of transcript with speaker labels.
Deep Dive
Oct 13, 2026
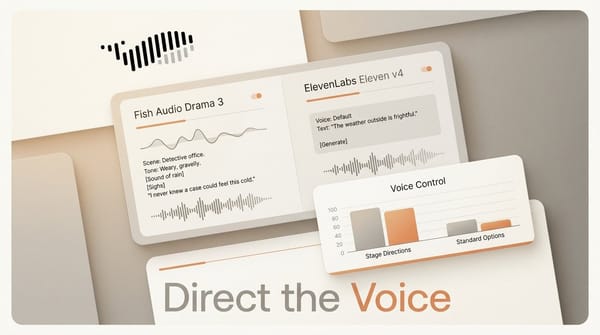
Fish Audio released Drama 3 on 13 October, a voice model you direct like an actor. We compare it with Eleven v4 on price and control, and show how to direct a scene in the app.
Deep Dive
Oct 1, 2026
OpenAI shuts down tts-1, tts-1-hd and gpt-4o-mini-tts on January 6, 2027. The replacement, gpt-realtime-2.1-mini, cannot serve the speech endpoint, returns no MP3 and drops onyx, nova and fable. We priced the switch, audited 9 creator tools and tested a free local drop-in.
Deep Dive
Sep 30, 2026
Hugging Face's new Open TTS Leaderboard puts the 82M-parameter Kokoro first in English. We read every model's license: in the multilingual and voice cloning views the #1 and #2 are non-commercial, and the first model you can ship is Qwen3-TTS at #3.
Deep Dive
Sep 28, 2026
ElevenLabs' Eleven v4 took first place on the Artificial Analysis Speech Arena at 1319 Elo on launch day. It costs $0.022 per 1,000 characters until 12 October, then $0.08: here is who should switch now and who should wait.

audiobooks
Jun 24, 2026
EbookAloud turns EPUB, DOCX, and TXT ebooks into M4B audiobooks using Kokoro AI voices for 0.99 to 5.99 dollars, with no subscription and no account.
AI Tools
Apr 15, 2026
Researchers published Darwin-TTS on April 15, 2026, a text-to-speech model that adds emotional expression to AI voice without any training, fine-tuning, or new data.
AI Tools
Apr 15, 2026
Google released Gemini 3.1 Flash TTS on April 15, 2026, a text-to-speech model that outperforms ElevenLabs v3 in quality benchmarks while offering a generous free tier.
Open Source
Mar 10, 2026
Fish Audio released S2, an open-source text-to-speech model trained on over 10 million hours of audio data spanning 50 languages. The model beats GPT-4o-mini-tts on the EmergentTTS-Eval benchmark with an 81.88% win rate, and ships with full weights, fine-tuning code, and a streaming inference engine