Deep Dive
Sep 30, 2026
DeepSeek Harness Desktop, a free MIT agent app for Mac and Windows, sends a structured session log with every request on DeepSeek's own model route by default. Our capture test shows what it carries, what it costs, and how to switch it off.

Deep Dive
Sep 9, 2026
DeepSeek shipped V4.1-Flash on 10 September: 552B multimodal MoE, MIT open weights, cache-hit prices down 57%, and every V4-Pro API call rerouted to it from 14 September.
Deep Dive
Aug 21, 2026
DeepSeek added image understanding to its cheapest fast model on August 21, 2026, billing images at standard V4-Flash rates with a free Files API.
AI
Aug 12, 2026
DeepSeek pushed its flagship V4 Pro to general availability on August 12, 2026, ending a preview that ran nearly four months. The GA build is a 1.6 trillion parameter MoE with a 1M-token context window.
Deep Dive
Jul 31, 2026
DeepSeek shipped the official production build of V4 Flash on July 31, 2026: an open-weight, MIT-licensed 284B-parameter MoE model with a 1M token context, native OpenAI Responses API and Codex support, and API output at $0.28 per million tokens.
Deep Dive
May 24, 2026
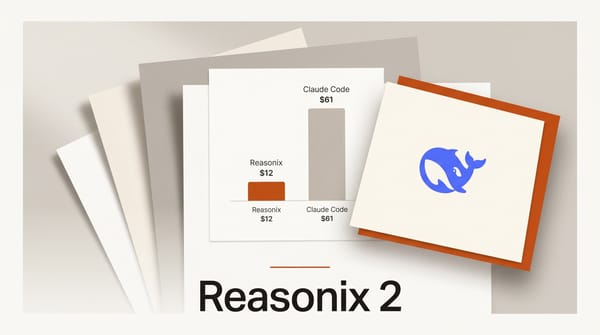
An open-source DeepSeek-native coding agent built around prefix-cache stability. A 435M-token session that costs $61 on Claude runs $12 on Reasonix.
Deep Dive
May 23, 2026
DeepSeek locked V4-Pro at $0.435 input miss, $0.003625 cache hit, $0.87 output per million tokens on May 23, ending the May 31 expiry and resetting the price floor for frontier reasoning APIs.
Deep Dive
May 15, 2026
DeepSeek-V4-Flash is the first local model competitive with frontier AI, making LLM activation steering practical for the first time. A guide for creators.